SpikingJelly
中文 | English
Contents
- Why SpikingJelly
- Installation
- Quick Start
- Core Capabilities
- Project Status and Version Notes
- License
- Acknowledgement
- Contributing
- Citation
Why SpikingJelly
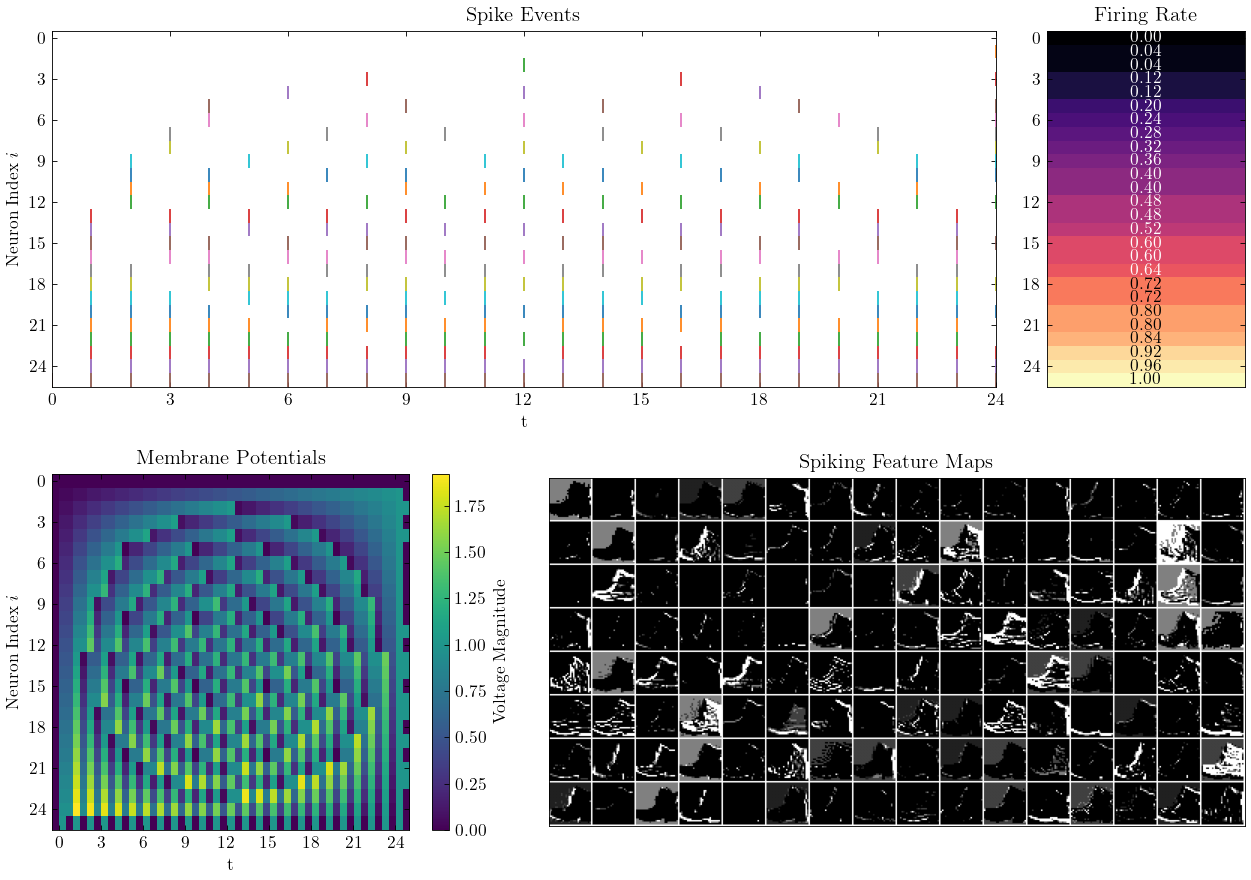
SpikingJelly is a PyTorch-native framework for spiking neural networks (SNNs), with support for large-scale SNN training and inference.
- Beginner-friendly API
- ANN2SNN conversion
- Event-based datasets
- Automatic operator execution: Torch, Triton and optional native CUDA
- Memory-efficient training, distributed execution, precision control
- Hardware deployment and framework exchange
Installation
Use uv in an activated virtual environment: Python >=3.11, Torch >=2.6.
First install PyTorch.
| Install | Command |
|---|---|
| PyPI release | uv pip install spikingjelly |
| PyPI pre-release | uv pip install --pre spikingjelly |
| Optional Triton (if missing) | uv pip install "spikingjelly[triton]" |
| Latest development source | uv pip install git+https://github.com/fangwei123456/spikingjelly.git |
Native CUDA (requires a toolchain; available after the corresponding V2 PyPI release):
SJ_BUILD_NATIVE_CUDA=1 uv pip install \
  --no-build-isolation --no-binary spikingjelly \
  --reinstall-package spikingjelly --no-cache "spikingjelly>=2.0.0"
See the installation guide for prerequisites, decision diagrams, other extras and troubleshooting. Unreleased changes require the development source.
Quick Start
Define an SNN in the same way that you would define any PyTorch model:
from torch import nn
from spikingjelly.activation_based import layer, neuron, surrogate

net = nn.Sequential(
    layer.Flatten(),
    layer.Linear(28 * 28, 10, bias=False),
    neuron.LIFNode(tau=2.0, surrogate_function=surrogate.ATan())
)
Next steps:
Core Capabilities
| Area | What SpikingJelly provides |
|---|---|
| SNN modeling | Activation-based SNN components: spiking neurons, surrogate gradients, stateful and stateless modules. Predefined SNN models. |
| Training workflows | PyTorch-native training flows, online-learning utilities, and ANN2SNN conversion |
| Performance | automatic Torch/Triton/native CUDA execution, FlexSN for customized neuron kernels, and mixed-precision training utilities (e.g., fp8) |
| Scaling | Memory-efficient training, and distributed training |
| Datasets | Neuromorphic datasets, and data preprocessing pipelines |
| Analysis | FLOPs / SynOps / memory-access profiling, and inference energy estimation |
| Interchange and deployment | NIR, Lava, and Lynxi-oriented exchange interfaces for neuromorphic workflows |
Operator Execution
Neuron execution is selected automatically from tensor device and execution path: CPU uses Torch; CUDA eager prefers compatible native CUDA, while Inductor expansion prefers Triton. CUDA Graph retains its pre-capture choice. No public neuron backend argument and no CuPy dependency are required. Low-precision state profiles can use Torch reference execution.
Pure Python wheels include Torch reference and optional Triton execution.
Optional native neuron, fused IF/LIF-Linear and packed/sparse projection builds
are described under Installation. Missing extensions use Torch reference
for projections; fused no-intermediate-spike performance requires the extension.
Use ordinary Linear/Conv plus memopt instead of retired SpikeLinear/SpikeConv.
Large-Scale SNN Systems
For large-scale SNN systems, SpikingJelly provides:
- Memory-efficient training with spike compression (
memopt) - Experimental distributed execution for multi-GPU workloads
- Precision policy tools for large-scale training and inference
- Spiking transformer components
Datasets
SpikingJelly includes the following event-based and neuromorphic datasets:
- ASL-DVS
- Bullying10K
- CIFAR10-DVS
- DVS-Lip
- DVS128 Gesture
- ES-ImageNet
- HARDVS
- N-Caltech101
- N-MNIST
- Nav Gesture
- SHD
- SSC
- Speech Commands
Each dataset supports raw event access and frame representations. See the neuromorphic datasets tutorial for the full workflow.
Interchange and Deployment
Export SpikingJelly models to neuromorphic hardware or other frameworks:
Project Status and Version Notes
Development / release policy:
Starting from SpikingJelly V2, release versions follow PEP 440 compatible,
SemVer-style MAJOR.MINOR.PATCH semantics. MAJOR marks compatibility
generations, MINOR adds backward-compatible functionality, and PATCH fixes
bugs. Python package pre-release spelling is used for V2 development releases,
for example 2.0.0.dev0, 2.0.0a1, 2.0.0b1, and 2.0.0rc1.
See CHANGELOG.md for the V2 release changelog.
Compatibility, migration, and older docs
- Before V2, SpikingJelly used a legacy
0.0.0.0.Xscheme: oddXtracked development versions on GitHub / OpenI, and evenXtracked stable releases published to PyPI. - If your project must stay on pre-V2 releases, pin dependencies with an upper bound such as
spikingjelly<2. - From
0.0.0.0.14, modules includingclock_drivenandevent_drivenwere renamed. See Migrate From Old Versions. - The default documentation points to the latest development version.
- If you rely on an older release, check bugs.md and switch to the matching documentation version.
Historical documentation:
License
SpikingJelly's project license is Apache-2.0. Third-party attributions and license terms are collected in LICENSES/NOTICE. See the license guide for scope and historical licenses.
Acknowledgement
Maintainers
Current maintainers (since July 2024):
Previous core maintainers (before July 2024):
Contributors
The full contributor list is on the contributors page.
Institutes
The main institutions behind SpikingJelly are Multimedia Learning Group, Institute of Digital Media (NELVT), Peking University and Peng Cheng Laboratory.
Community and related links
- Documentation
- Contributing Guide
- Issues and development discussion
- OpenI mirror
- Community Jupyter tutorials in Chinese
Contributing
We welcome issues, pull requests, documentation improvements, and translations.
- Read the Contributing Guide.
- Check issues for ongoing work.
- API docs are not fully bilingual yet; translation contributions are especially welcome.
Citation
Publications using SpikingJelly are listed on the documentation page. The source of truth in this repository is publications.json.
If you use SpikingJelly in your work, please cite:
@article{
doi:10.1126/sciadv.adi1480,
author = {Wei Fang and Yanqi Chen and Jianhao Ding and Zhaofei Yu and Timothee Masquelier and Ding Chen and Liwei Huang and Huihui Zhou and Guoqi Li and Yonghong Tian},
title = {SpikingJelly: An open-source machine learning infrastructure platform for spike-based intelligence},
journal = {Science Advances},
volume = {9},
number = {40},
pages = {eadi1480},
year = {2023},
doi = {10.1126/sciadv.adi1480},
url = {https://www.science.org/doi/abs/10.1126/sciadv.adi1480},
eprint = {https://www.science.org/doi/pdf/10.1126/sciadv.adi1480}
}