English | 简体中文 | Español | हिन्दी | Português | 日本語 | Русский | 한국어
An open-source runtime for colonies of AI agents that do real business work.
Tell a queen agent what you need. She does the first piece herself to learn what the job takes, then hands the rest to as many parallel workers as it needs. Every result lands in a shared tracker you can query, audit and resume from.
A real run. Only the typing and the waiting are sped up, and the badge says by how much. Watch the full run (MP4).
What you just watched
A growth team preparing a Show HN wants to know how five developer tools' own launches did on Hacker News. Here's what Hive did with that one message:
- You hand it to a queen. Queens are long-lived agents with a role (here, Head of Growth) and their own memory and tools.
- She asks the one question that changes the answer: every launch post, or only each product's original launch? You pick every launch, and she carries on.
- She proposes a colony, and you approve it. Five products means five parallel jobs, so the chat becomes a colony: the queen plus as many worker agents as the work needs.
- She does one herself. She takes PostHog first, works out what counts as a genuine launch post rather than a passing mention, checks the numbers against the Hacker News API, and saves the method as a reusable skill.
- She fans out. A playbook starts one worker per product. Each follows her skill and writes its result to the colony's tracker, a shared SQLite table.
- She checks every row before she answers, and fixes one. Cal.com's worker counted a post from its old name, Calendso, but that post wasn't a Show HN, Launch HN or YC launch. She clears the row, and the chart shows Cal.com as not found rather than zero.
None of this was wired up in advance. There's no workflow graph to draw: the queen shapes the colony as the work unfolds, and a tracker on disk, not a context window, keeps count of what's done and what's left.
Quick start
You'll need Python 3.11+, Node.js 20+ and git. The quickstart installs uv and ripgrep if they're missing, and offers to install Node.
And a model. The quickstart sets up any of these:
- an API key from Anthropic, OpenAI, Google Gemini, Groq, Cerebras or OpenRouter
- a coding subscription you already pay for: Claude Code, OpenAI Codex, Kimi Code, MiniMax, Z.AI or Antigravity
- Hive LLM
- a local model through Ollama, with no key at all
git clone https://github.com/aden-hive/hive.git
cd hive
./quickstart.sh          # macOS / Linux
.\quickstart.ps1         # Windows (PowerShell 5.1+)
The quickstart creates a single Python environment for the workspace, stores your API key encrypted under ~/.hive, asks which model to use, builds the dashboard and opens it at http://127.0.0.1:8787. Next time, run hive open from the repository.
[!NOTE] Hive is a
uvworkspace, not a pip package.pip install -e .installs a placeholder that won't run; use the quickstart.
Then type a task on the home screen and choose the queen to give it to, or open the Prompt Library and send a ready-made prompt straight to the queen it was written for.
How it works
flowchart LR
    You(["You"]) -->|"describe the outcome"| Queen["Queen
(persistent agent)"]
    Queen -->|"proposes a colony,
you approve"| Pilot["Pilot
(one unit, done by the queen)"]
    Pilot -->|"saves the method"| Skill["Skill + playbook"]
    Skill -->|"run_worker / run_playbook"| W["Worker clones
in parallel"]
    W -->|"tracker_upsert"| T[("Tracker
shared SQLite")]
    T -->|"SQL: what's done,
what's left"| Queen
    Queen -->|"checked answer"| You

    style Queen fill:#ffb100,stroke:#cc5d00,color:#333
    style T fill:#fff3d6,stroke:#cc5d00,color:#333
    style W fill:#ff9800,stroke:#cc5d00,color:#fff
Hive has one execution primitive: the agent loop. The queen is one, and every worker is a clone of it with its own task, a narrower set of tools and a strict budget. Orchestration is a tool call, not a compiled graph:
run_workerfans tasks out and returns at once, so the queen keeps talking to you while workers run. Four run at a time by default; the rest wait their turn. Each worker's report arrives in the queen's conversation as a new turn.- The tracker is the colony's shared state. The queen defines the table and which columns workers may write, workers upsert one row per unit of work, and the queen checks progress with SQL. It's a file on disk:
~/.hive/colonies//tracker/tracker.db. run_playbookruns a proven method over every row, with retries and backoff, rate-limited lanes, and a dead-letter list for rows that keep failing. "What's left" is always a fresh query of the tracker, so re-running a playbook picks up where it stopped.
The architecture overview goes deeper: the loop, the tool surface, memory, human oversight, and how state survives a crash.
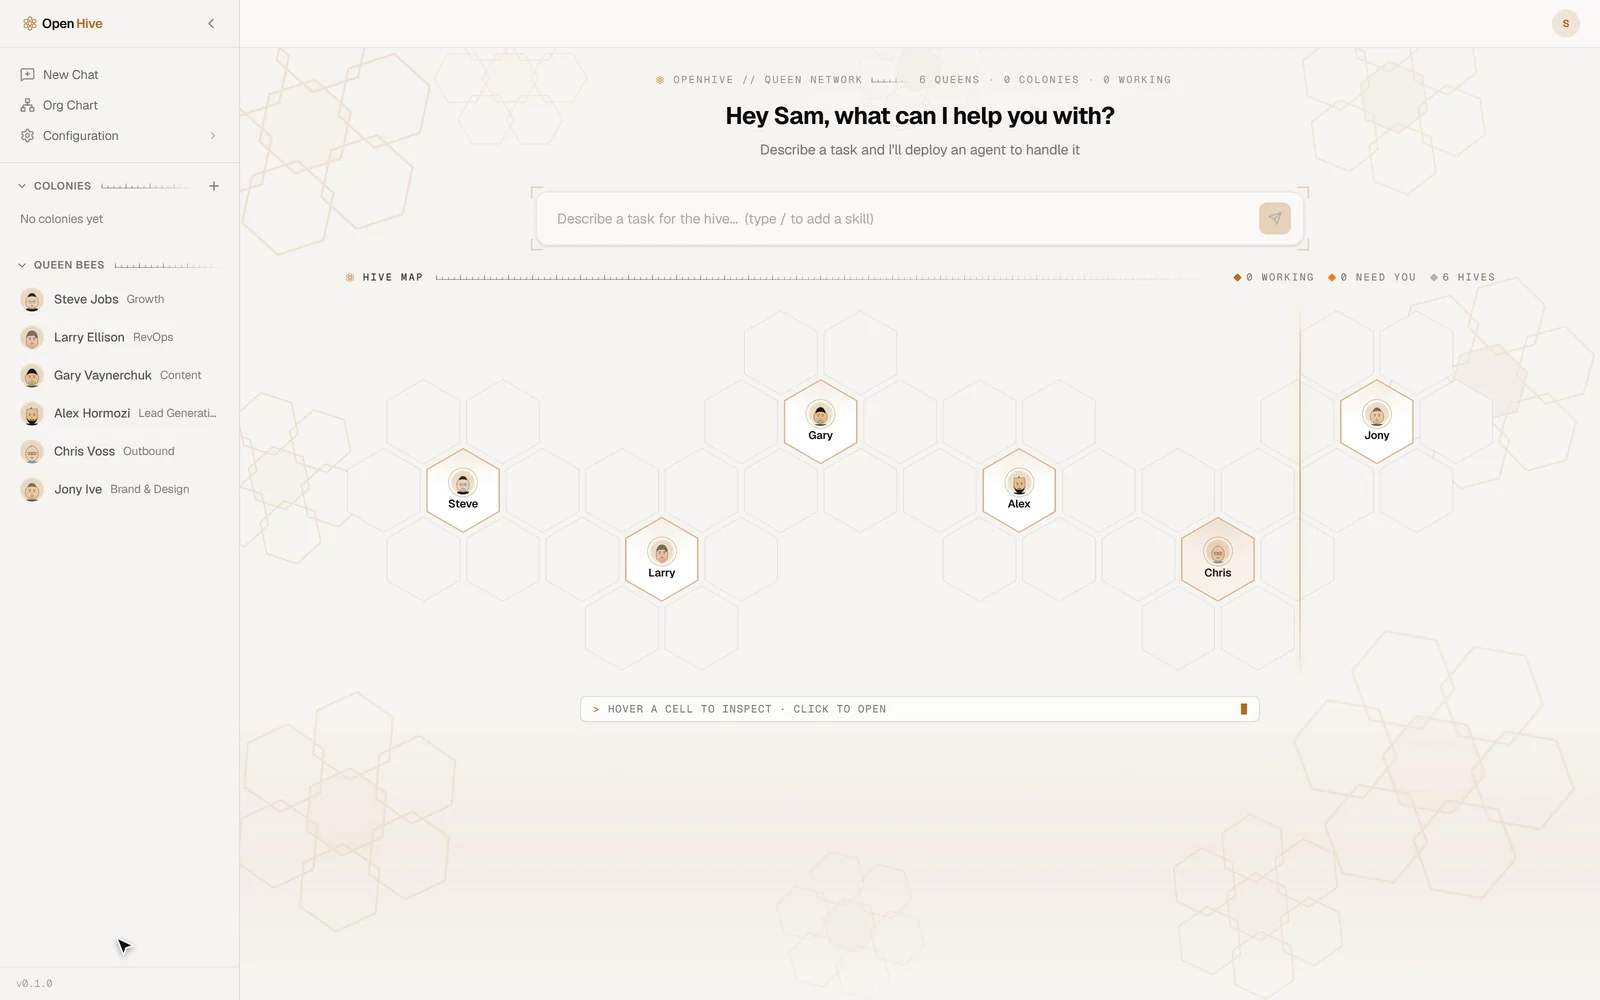
Home. Your queens and their colonies on one map. Describe a task and choose who takes it.
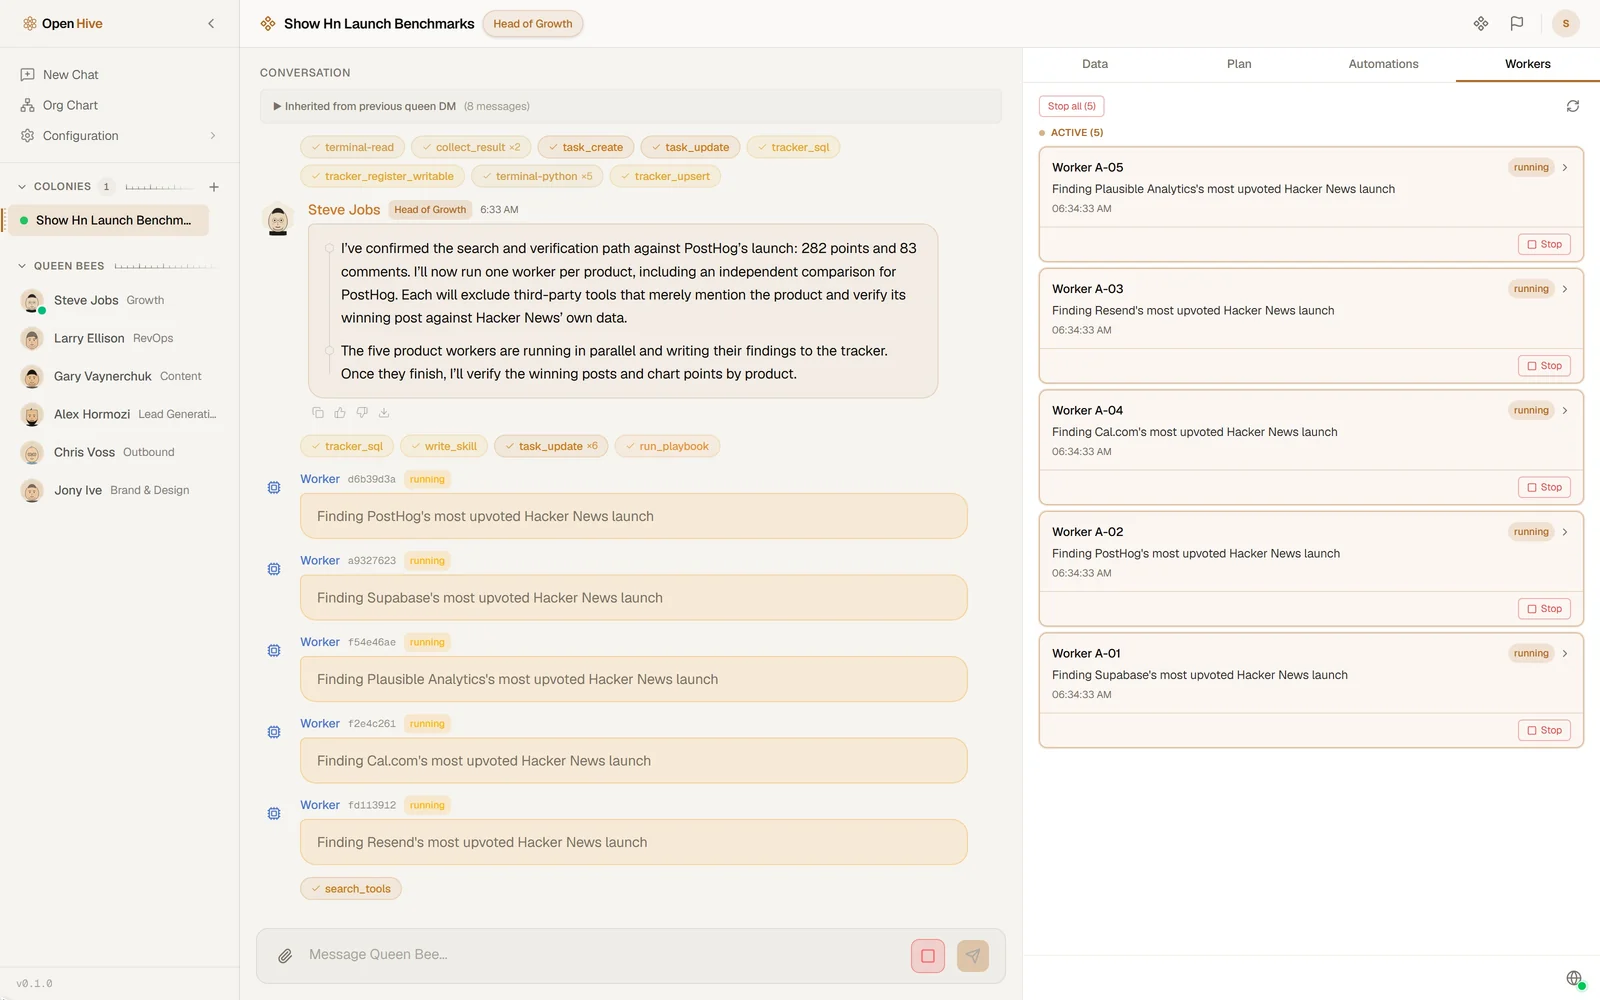
Workers. One per unit of work, each with its own task and budget, all reporting to the queen.
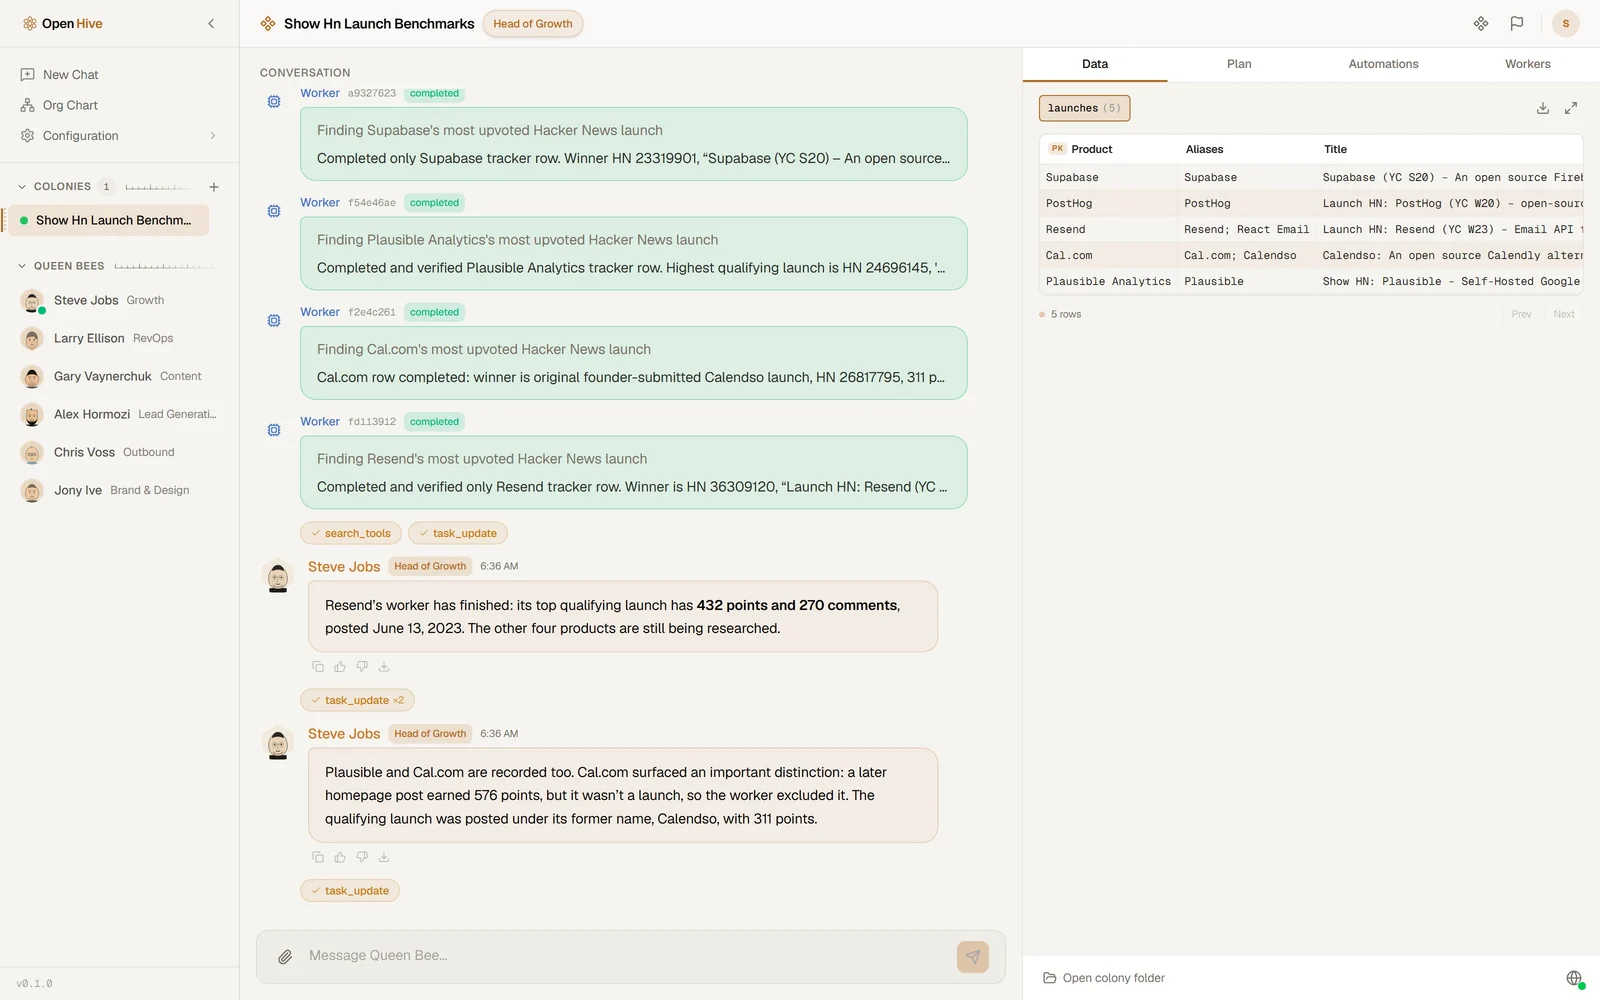
Tracker. Results land in a shared table as workers finish, ready to query, export or resume from.
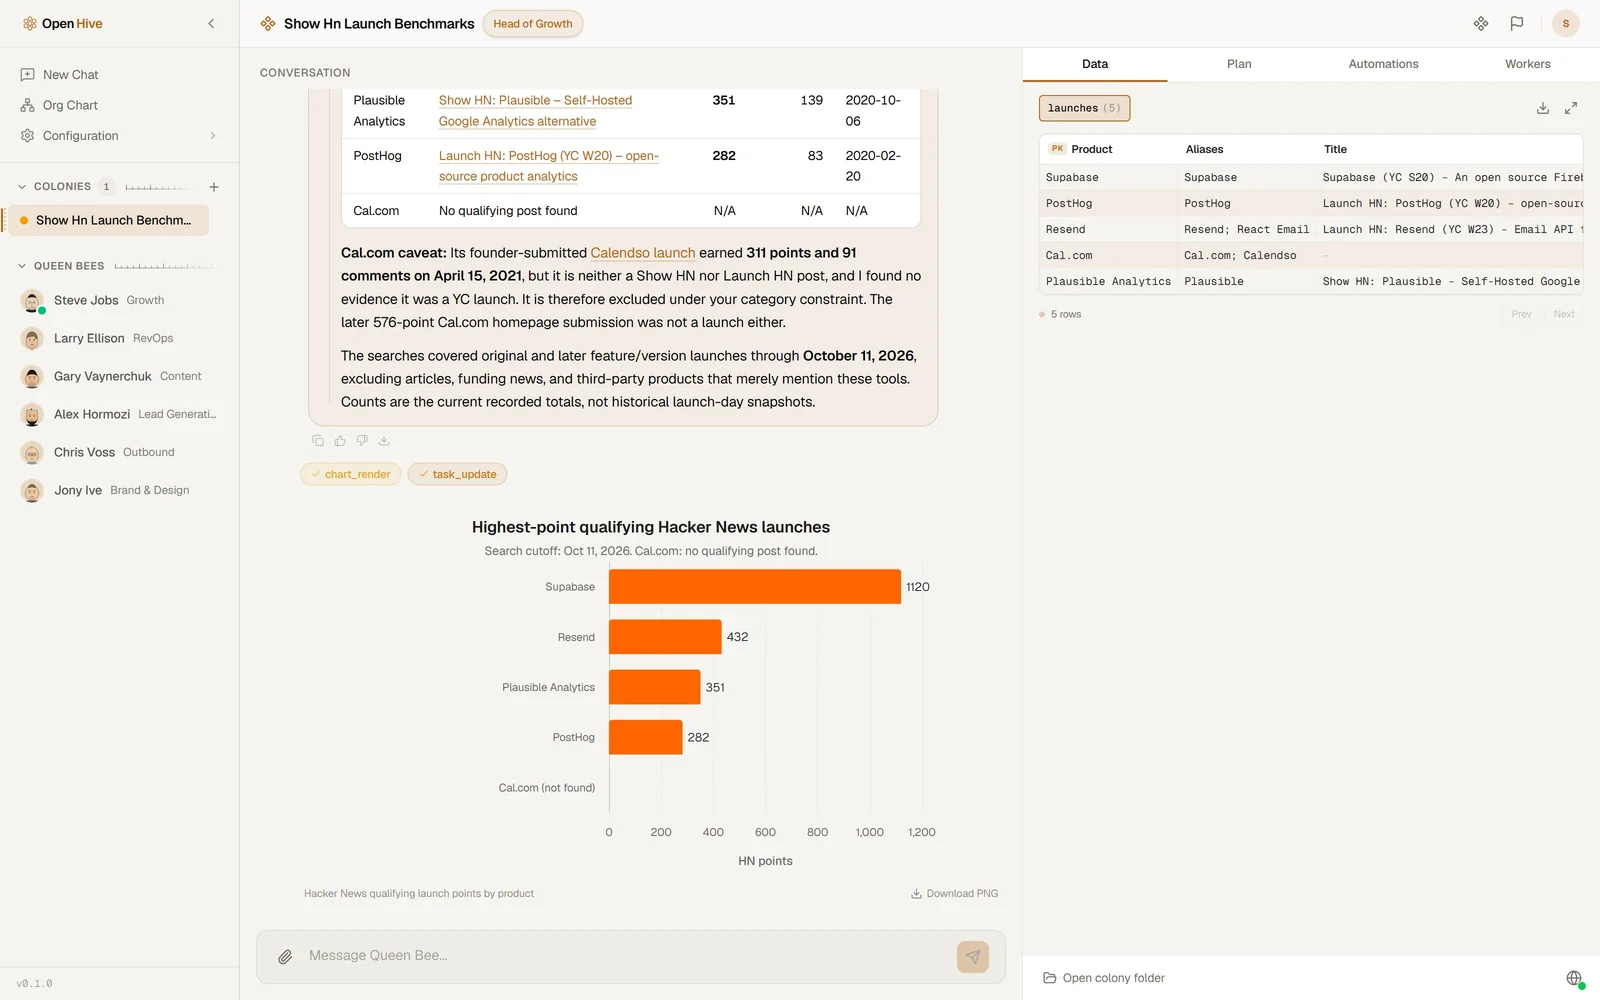
Result. A checked answer with sources and a chart, right in the chat.
What's inside
Queens with a job and a memory. Hive ships thirteen persona queens. Six are active out of the box (Growth, RevOps, Content, Lead Generation, Outbound, and Brand & Design); hire the rest from the Org Chart, or create your own. Each one keeps notes in markdown memory as she works, and relevant past conversations are recalled into her context automatically.
Built-in tools that run in-process. Shell commands and background jobs, file editing, fast code search, PDFs, attachments and images, web scraping, charts (ECharts and Mermaid), CSV files, and image generation through Hive LLM. They run inside Hive itself, with no tool servers to start.
Your browser, driven by your agents. The Hive Browser Bridge extension lets agents work in your own Chrome, where you're already logged in. Each worker gets its own tab group.
Skills. Reusable instructions in the open Agent Skills format. Hive ships with a set, queens write new ones once a method proves out, and you manage them all in the Skills Library.
Any MCP server. Add one with hive mcp add, and its tools join the same allowlists as the built-ins. The full integration catalog in tools/ (GitHub, Gmail, HubSpot, Slack, Notion and many more) runs as one; see docs/tools.md.
Runs while you're away. Colonies can wake themselves on cron, interval or webhook triggers. Sentinel, opt-in per colony, watches a queen whenever she stops: it nudges her on, or escalates to you through the Hive inbox, Telegram or Slack, and she picks up as soon as you reply.
Built to survive. Every agent saves its state to disk and resumes exactly where it stopped after a crash or restart. Large tool results spill to files instead of flooding the context, long sessions compact themselves, stuck or looping turns get caught, and every worker runs under a hard tool-call budget.
Any model. Anything LiteLLM supports, including OpenAI, Anthropic, Gemini, OpenRouter, Hive LLM, any OpenAI-compatible endpoint and local models through Ollama. Workers can run on a different model than their queen, and text-only models still see images through a vision fallback.
Is Hive for you?
Hive earns its keep once the model is no longer the hard part, and everything around it is:
- A process with many similar units of work, such as leads, accounts, tickets, repositories or documents, that you want done in parallel and done the same way every time.
- Work that runs for hours or on a schedule and has to survive a restart.
- Results you need to check, query and audit, not just read in a chat.
- A human who stays in charge of the decisions that matter.
For a single prompt or a one-off script, a plain agent is simpler.
Documentation
- Getting started: setup in more detail
- Architecture overview: how colonies, the loop, tools and memory fit together
- Key concepts: colony, queen, workers, coordination, the loop, goals and outcomes, how colonies improve
- Tools: built-in tools, MCP servers and the integration catalog
- Configuration and the developer guide
- Roadmap: what V1 ships and what's still open
- docs.adenhq.com: hosted documentation
FAQ
Which models does Hive support? Any provider LiteLLM supports, plus any OpenAI-compatible endpoint. The quickstart sets up the common ones, including coding subscriptions such as Claude Code and OpenAI Codex; docs/configuration.md covers the rest.
Can I run it with local models?
Yes. Choose Ollama in the quickstart, or set a model such as ollama/llama3 with Ollama running locally.
How is this different from other agent frameworks? Most frameworks ask you to design a graph of agents and wire up their inputs and outputs. Hive has one kind of agent: the queen is an agent loop, and every worker is a clone of it. Orchestration happens at runtime through tool calls, and agents coordinate through a shared SQL tracker instead of passing messages along edges. Persistence, resume, budgets, compaction and oversight live in that one loop, so every agent gets them.
Where does my data live?
On your machine. Sessions, colonies, trackers and memory are plain files under ~/.hive (or wherever HIVE_HOME points), and API keys are stored there encrypted.
How do I keep costs under control? Every worker runs under hard limits on turns and tool calls, so a stuck worker stops by itself, and the number of workers running at once is capped. Every model call is metered. There are no spending limits in dollars yet.
Can agents use my own tools and APIs? Yes: through the built-in shell and browser, through any MCP server you add, and through skills that teach them your procedures.
Is Hive open source? Yes, under the Apache License 2.0.
Contributing
Contributions are welcome, especially tools, integrations and skills (#2805). Read CONTRIBUTING.md first, and get assigned to an issue before you open a pull request: comment on the issue and a maintainer will assign you. Issues with reproduction steps or a concrete proposal get priority.
Community
- Discord for questions, feature requests and discussion
- X / Twitter and LinkedIn for updates
- HoneyComb: a community market that tracks which jobs AI agents are automating. Go long or short on a job with compute tokens, not money.
We're hiring in engineering, research and go-to-market. See open positions.
Security
To report a vulnerability, see SECURITY.md.
License
Apache License 2.0. See LICENSE.
Star history
Made with 🔥 passion in San Francisco