Jarvis
Your intelligence. Your hardware.
A private, local-first voice assistant that lives on your computer.
Talk naturally, as if Jarvis were a third person in the room.
Voice-first · Local AI · Personal memory · No subscription
Download Jarvis → · Get started · Explore the app · Support the project
An assistant that lives with you, not in the cloud
Jarvis is built to be part of the conversation. Talk through an idea, discuss plans with a friend, then ask “Jarvis, what do you think?” While listening, it keeps a short, temporary rolling transcript of nearby speech so it can join an ongoing conversation using what was just discussed.
Address Jarvis by name anywhere in a sentence and follow up naturally. Speech recognition, language models and speech synthesis run on hardware you control.
Your conversation and all data stays solely on your computer. Sensitive information is redacted before it reaches model context or the saved diary, even though both are local, to ensure the security of your private information. Web search, weather and connected tools use the network but send only what is necessary when you ask for those capabilities.
A voice, a face, and a place in the conversation.
Quick Install
1. Download the app. Choose your platform from GitHub Releases.
| Platform | Package | Open |
|---|---|---|
| macOS · Apple Silicon | Jarvis-macOS-arm64.zip |
Extract, move to Applications, then right-click → Open |
| macOS · Intel | Jarvis-macOS-x64.zip |
Extract, move to Applications, then right-click → Open |
| Windows · x64 | Jarvis-Windows-x64.zip |
Extract, then run Jarvis.exe |
| Linux · x64 | Jarvis-Linux-x64.tar.gz |
Extract, then run ./Jarvis/Jarvis |
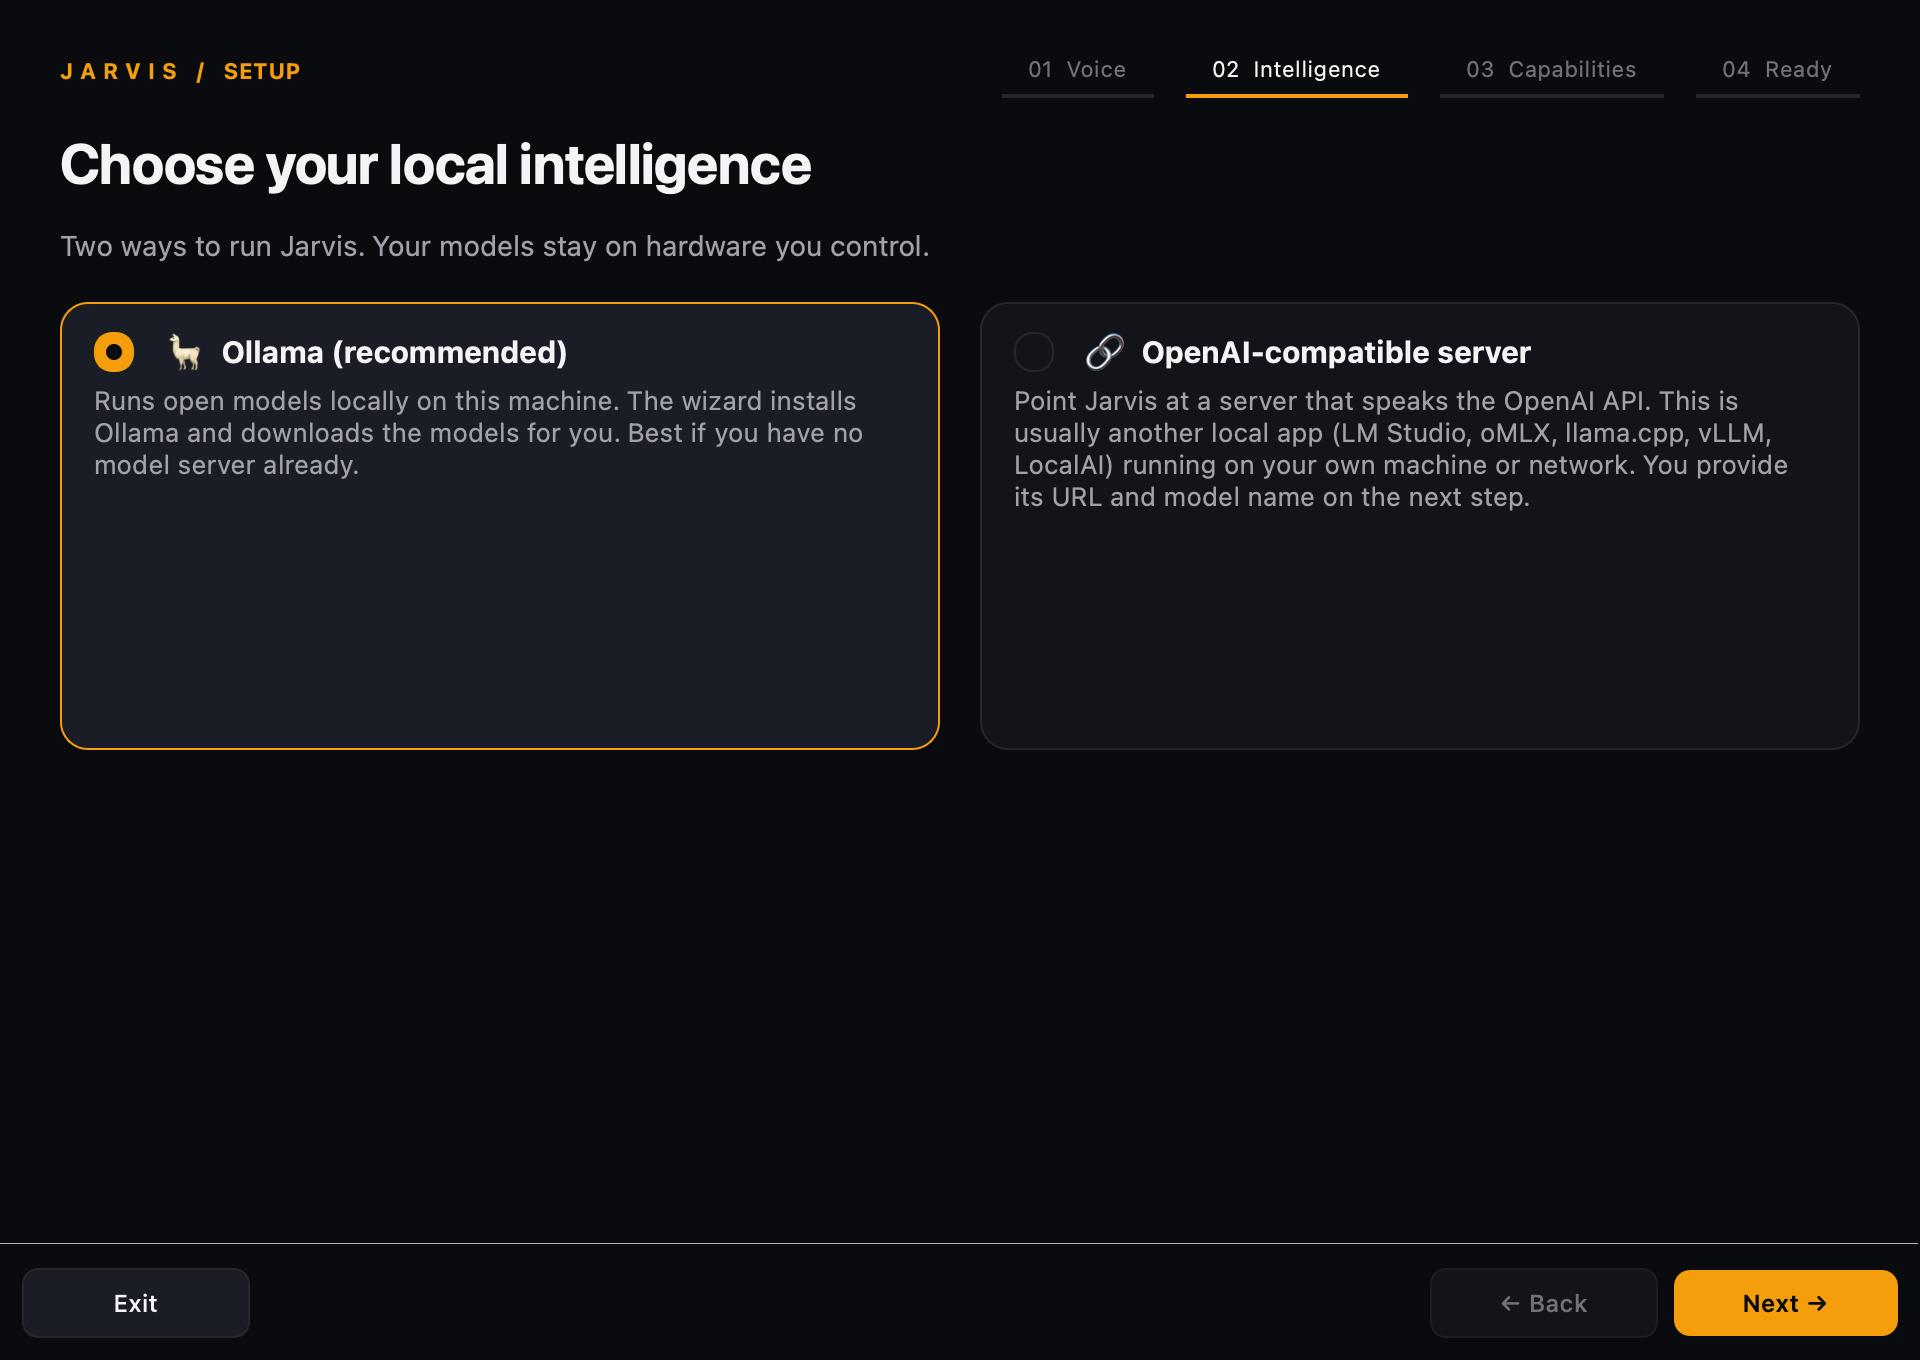
2. Choose your local models. The setup wizard guides you through speech recognition and a model server. Use Ollama, or connect an OpenAI-compatible server you already run, such as LM Studio, oMLX or llama.cpp.
3. Make it yours. Allow microphone access and let the first model downloads finish. When Jarvis reports that it is listening, try:
“Jarvis, help me think through my day.”
Right-click the face or use the tray menu to open Chat. Text replies are silent.
Hardware and model choices
Memory needs depend on model size, quantisation, context length and speech recognition. Both Ollama and OpenAI-compatible setup show a memory budget; you can edit estimates for models served through an OpenAI-compatible endpoint. Smaller models trade capability for lower resource use.
| Starting point | Chat model |
|---|---|
| Smaller hardware | qwen3.5:0.8b |
| Constrained memory | gemma4:e2b |
| Default | gemma4:e4b |
| Larger local setup | qwen3.8:27b |
Budget memory for Whisper and, when different from chat, the fast model used for voice intent and tool routing. Apple Silicon uses unified memory; other GPUs use dedicated VRAM. Setup budgets chat and fast together alongside the selected Whisper model, using E2B for fast tasks when it fits or sharing E4B across both roles to save memory. Apple Silicon estimates reserve memory for macOS. Saved model choices are preserved, and insufficient memory shows CPU fallback guidance.
What you can do
- A third person in the room. Bring Jarvis into an ongoing conversation with friends, talk through a problem aloud, or ask it to weigh in on a decision. “Jarvis, what do you think?” draws on the recent discussion, not just that one sentence.
- Remember beyond one session. Ask about past conversations, preferences and plans. Browse your local diary and knowledge graph in the Memory Viewer.
- Get things done. Built-in tools cover web search, weather, time, screenshot OCR, file access, nutrition tracking and optional location awareness.
- Connect your own tools. MCP servers add browser automation, smart-home controls and other integrations.
- Dictate into other apps. Hold a hotkey, speak, then release to paste locally transcribed text. See the platform limitations first.
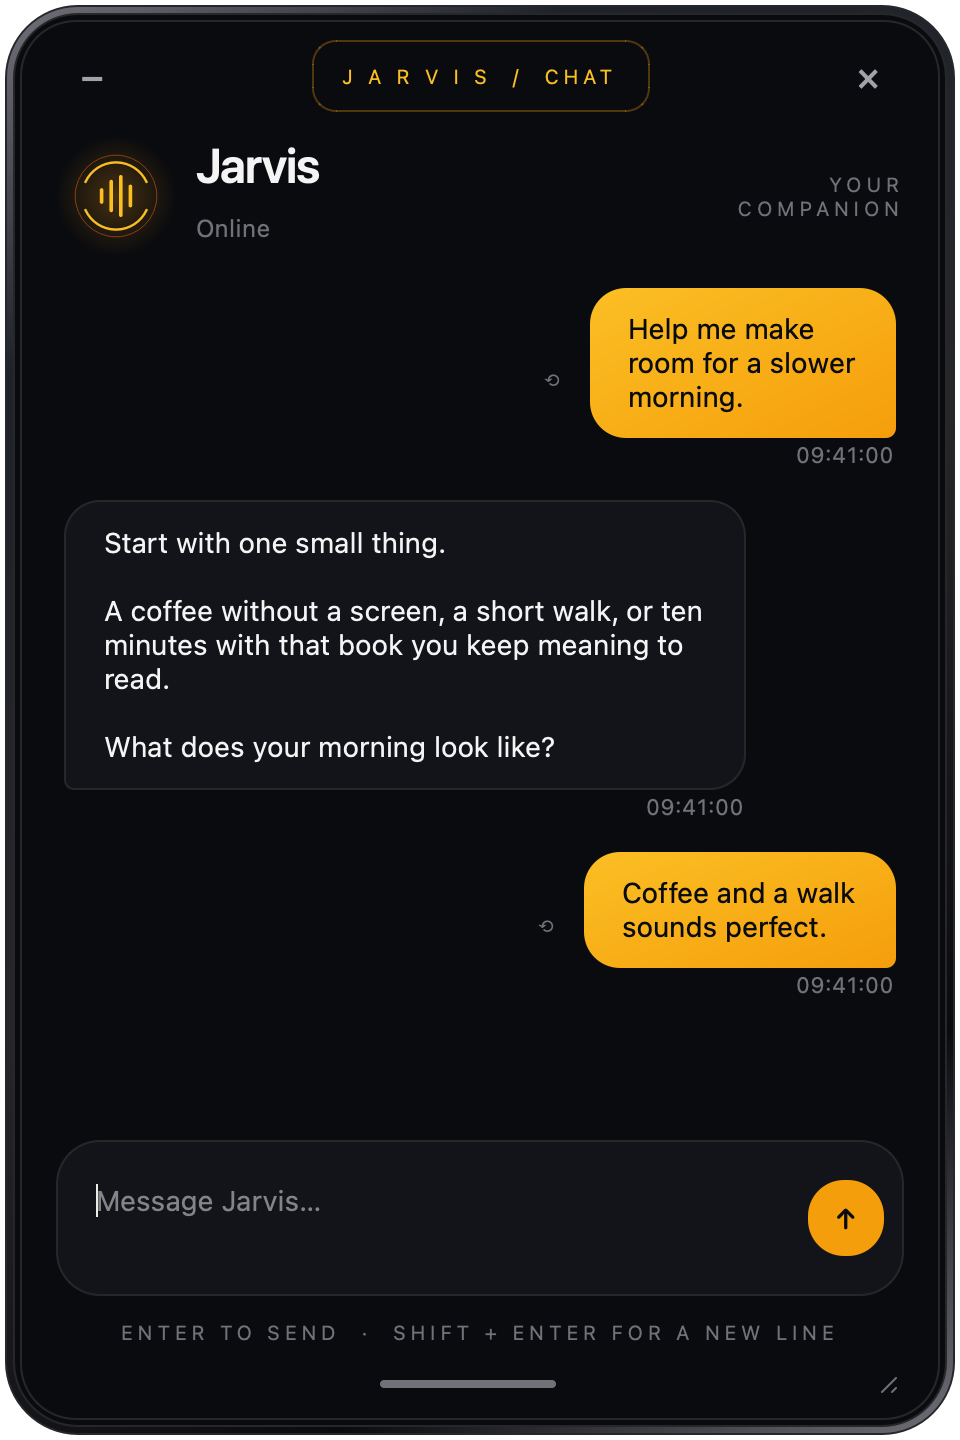
- Type when you need to. The companion chat shares your voice conversation and memory. Text replies are silent, and you can rewind a sent message to regenerate from that point.
Bring Jarvis into the discussion
You: We could have a picnic tomorrow.
A friend: Depends on the weather. Should we plan something indoors instead?
You: Jarvis, what do you think?
Jarvis can use the recent conversation to understand that you are asking about the weather for the picnic, rather than treating the last sentence as an isolated question. This is the experience it is built around. Personalised requests can also draw on saved conversation history when no external tools are needed. How reliably it understands the context depends on speech recognition and your chosen model; see the evaluation results.
Inside Jarvis
Keep setup, activity and settings within reach.
A guided start
Choose the runtime that fits your machine. Setup walks through local models, speech and optional capabilities without requiring you to edit a configuration file.
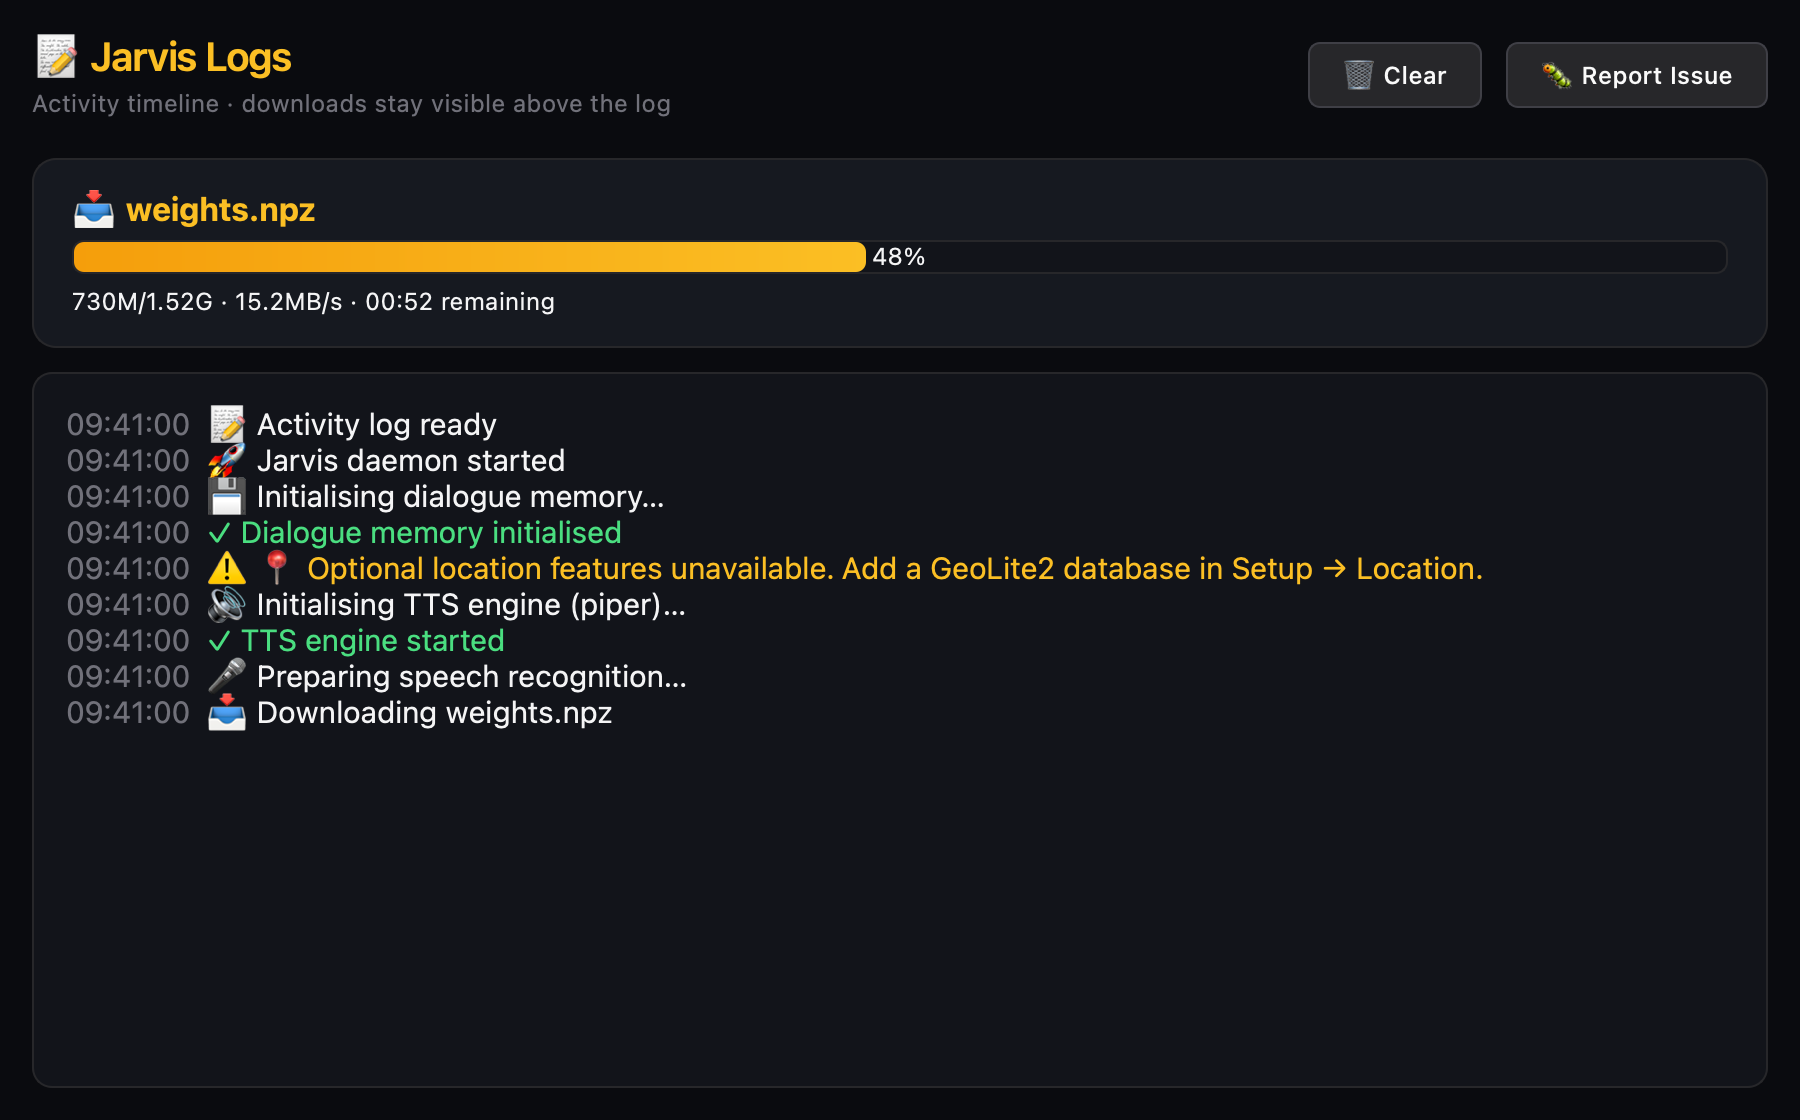
Progress you can actually follow
The activity timeline keeps ordinary events readable. Downloads have a separate card with transferred bytes, percentage, speed and remaining time when the downloader provides them. Loading and warmup are distinct stages.
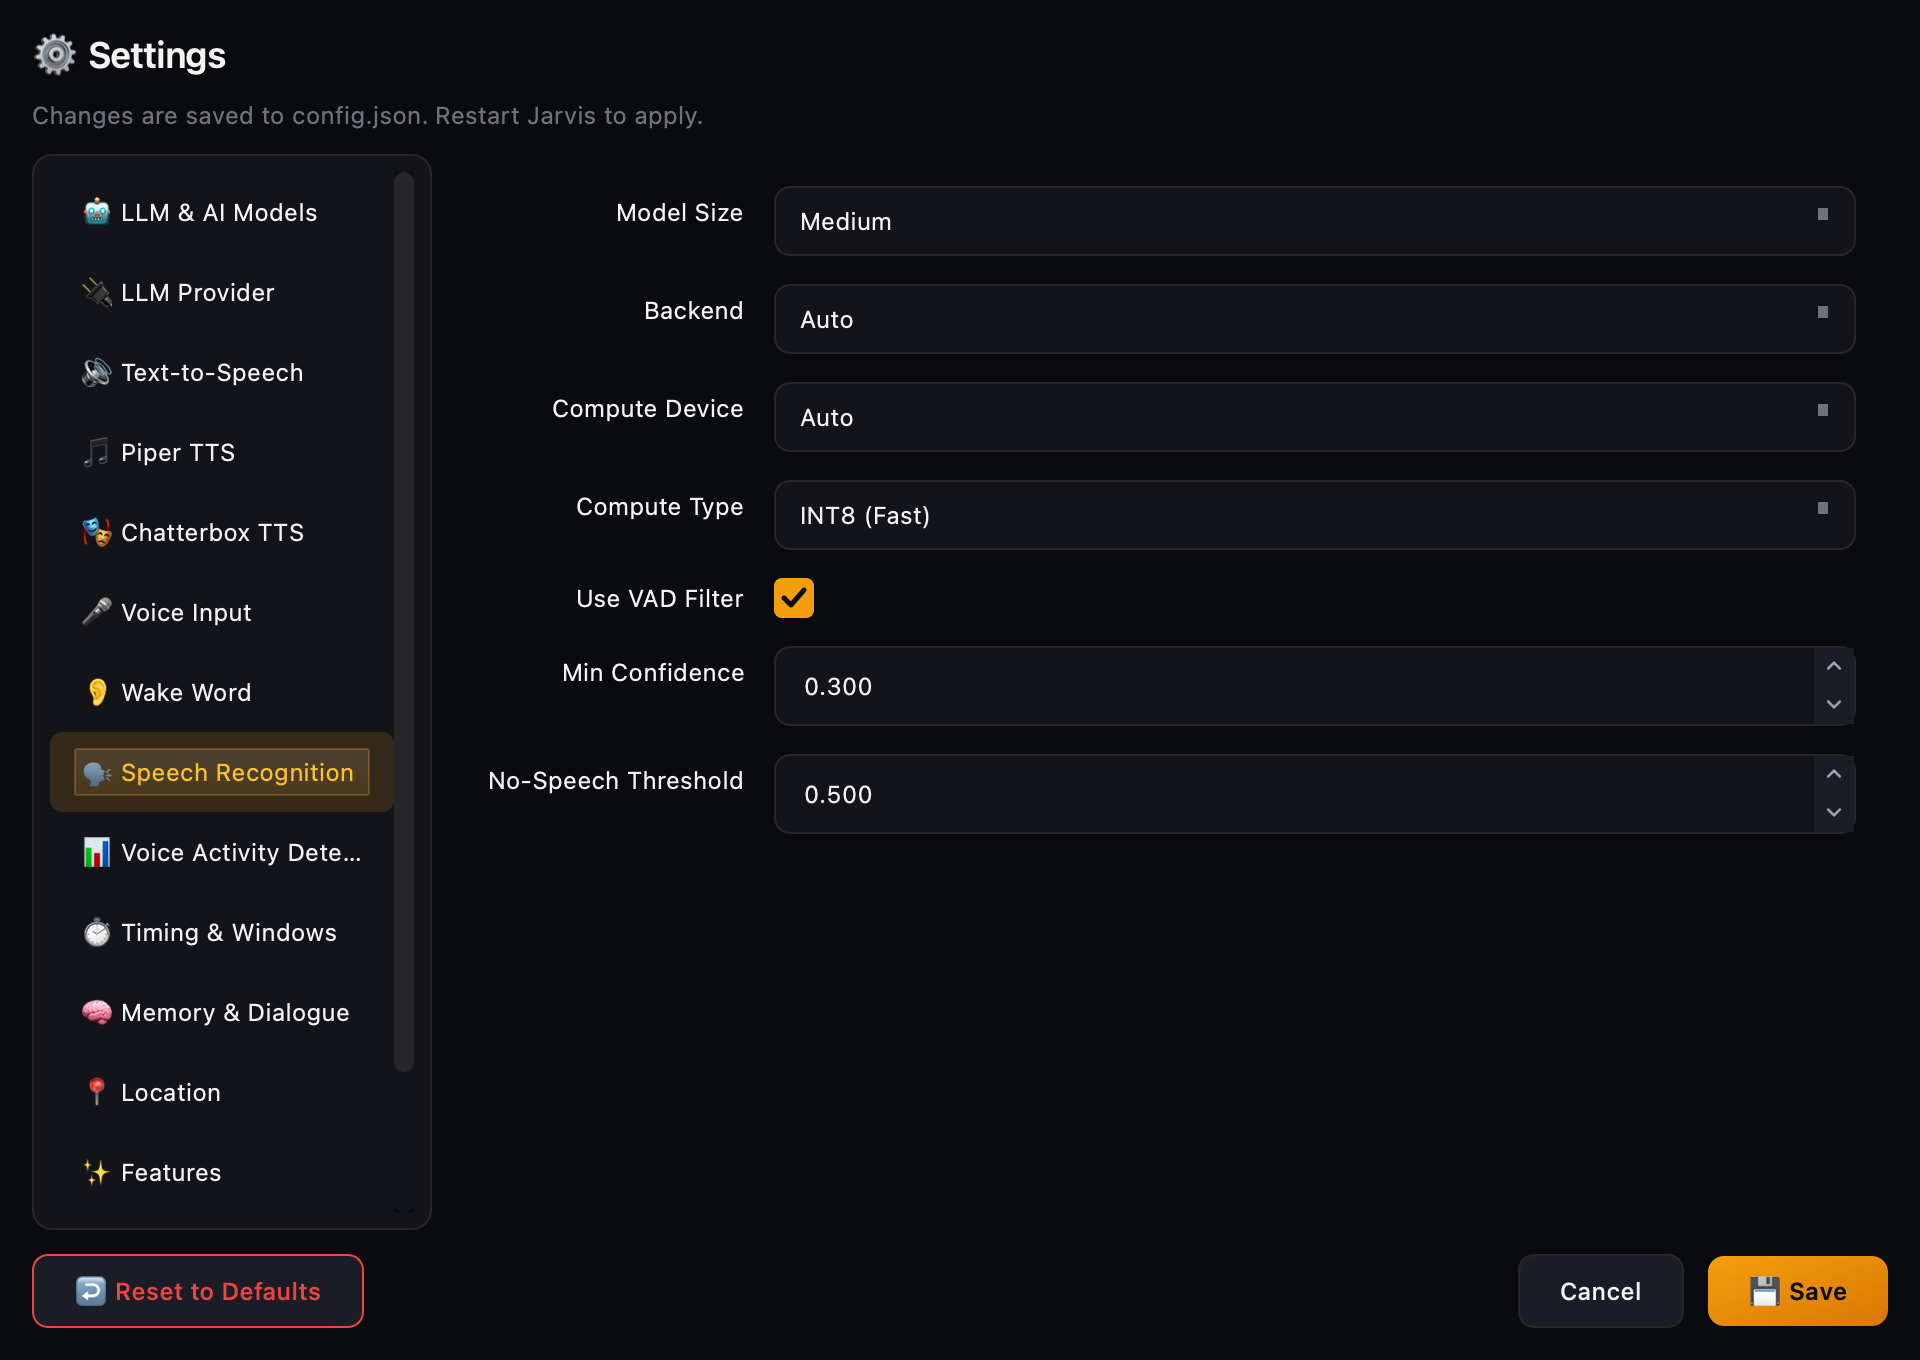
Your setup, without the JSON
Choose models, tune speech recognition, configure tools and enable Low Power Mode from Settings in the tray menu.
A quiet companion to voice
Open Chat for silent replies in the same conversation. Pause Voice Listening stops room transcription during meetings while chat and dictation stay available.
Known limitations
Jarvis is developed primarily on macOS. Windows and Linux behaviour may differ. See the evaluation results for tested capabilities.
- Accuracy and speed depend on your models and hardware. Smaller models can miss parts of complex requests, and slow speech recognition can drop utterances.
- Dictation is unavailable on macOS 26+ (#172). Linux dictation requires X11, with limited Wayland support.
- Spoken “stop” can be mistaken for echo while Jarvis is speaking (#24).
- Very large web pages cannot be read. Page downloads have a 2 MiB limit.
- No mobile app is available (#17).
Configuration
Most people can use Settings from the tray. Advanced setups can edit ~/.config/jarvis/config.json.
Open the configuration guide →
The guide covers local model servers, speech recognition, Low Power Mode, voices, dictation, location, MCP integrations and troubleshooting.
Dictation at a glance
| Platform | Default hotkey |
|---|---|
| Windows | Ctrl + Win |
| macOS, where supported | Ctrl + Option |
| Linux | Ctrl + Alt |
Hold to record and release to paste. Double-tap for hands-free recording. Optional filler-word removal, a custom dictionary and dictation history are available in Settings. macOS needs Accessibility permission; Linux requires X11, with limited Wayland support.
Bring your own tools
Connect MCP servers for browser automation, Home Assistant, GitHub, databases and more. Credentials and network access depend on the tools you choose. Review a server's permissions before enabling it.
Integration examples and server settings →
Troubleshooting
-
🔇 Speech output unavailable: A voice-model or dependency failure disables speech output for the current run. Check the reason in Logs, correct the voice model settings or missing dependencies, then restart Jarvis.
-
🔊 Piper download interruptions: Connection resets and timeouts receive bounded retries. If they persist, check connectivity and restart Jarvis; completed voice files are retained. Certificate errors require correcting the trust configuration.
-
📥 Whisper download failures: Faster-whisper downloads run in a separate process with a five-minute limit. If a download crashes or times out, restart Jarvis to resume it; cached models stay available offline.
-
🎤 Whisper cache errors: Jarvis attempts one clean download recovery per startup. If it fails, check connectivity and free disk space, then follow the printed cache guidance and restart. Device fallbacks retain files downloaded during recovery.
No default microphone found
Select an available microphone in Jarvis Settings, or set a default recording input in your system Settings, then restart Jarvis. Jarvis keeps the selected input throughout startup and does not choose another microphone automatically when the default is unavailable.
Bluetooth microphone will not start
Select the headset's microphone/input profile in Settings, not its playback device. Jarvis uses the selected input for listening and dictation, tries compatible mono, stereo and device-native capture formats, then converts multichannel input to mono for speech recognition. If that input is unavailable, select another microphone in Settings. If capture still fails, check that the microphone works in your system's recorder and share the error from Logs; Bluetooth driver/profile limitations can still prevent capture.
Linux says Listening, but never hears speech
Check Logs for missing-callback or silent-input warnings. Verify the recording source and mute state in PipeWire/PulseAudio, and select a microphone rather than an output monitor. Enable voice_debug in Settings for capture-level diagnostics. See the troubleshooting guide.
Downloads look paused
Open Logs from the tray. The progress card shows transfer details when available and elapsed waiting time when updates pause. After downloading, loading the model into memory is a separate step.
Warmup passed, but a request timed out
Warmup checks model loading with a small probe, not a full request. Voice intent detection has a separate timeout from chat. Check the limit shown in the log and your local server's responsiveness.
The Mac gets warm, or I want lower background usage
Enable Settings → Features → Low Power Mode. It skips LLM startup warmup and shortens Ollama model residency while keeping speech recognition ready. The first model request after idle may take longer.
For Developers
Run from source
git clone https://github.com/isair/jarvis.git
cd jarvis

# macOS
bash scripts/run_macos.sh

# Windows (PowerShell, with Micromamba)
pwsh -ExecutionPolicy Bypass -File scripts\run_windows.ps1

# Linux
bash scripts/run_linux.sh
Running from source also enables Chatterbox TTS. Piper works in both packaged and source installations.
Refresh the screenshots
With the desktop dependencies installed in your Python environment:
PYTHONPATH=src python scripts/capture_readme_screenshots.py
The capture script uses the real widgets and illustrative data, isolates configuration in a temporary directory, and blocks network connections and background workers. It does not launch the daemon or use personal conversations. Keep screenshots on separate rows at readable widths.
Evaluation results · Report a bug · Contribute
Privacy & Storage
Local AI is the default, not a paid upgrade. No cloud AI service is required.
- Local file access: limited to your home directory. Directory listings identify symbolic links and reject patterns that reach external directories.
- Conversation memory: stored locally under
~/.local/share/jarvis. - Sensitive information: redacted before model context and saved diary entries. The in-memory chat still shows what you typed.
- Network boundaries: model downloads, web tools and enabled integrations can make network requests. An external model endpoint receives the requests you send to it.
Reduce optional network access
Use a local model endpoint, download the required models first, disable web tools and leave MCP integrations empty. These settings turn off search and automatic location detection:
{
  "web_search_enabled": false,
  "wikipedia_fallback_enabled": false,
  "brave_search_api_key": "",
  "mcps": {},
  "location_auto_detect": false,
  "location_cgnat_resolve_public_ip": false,
  "location_enabled": false
}
These options are not a network firewall. Other online tools and app update checks may still use the network; enforce network restrictions separately if required.
Support
Jarvis is free for personal use. For commercial use, get in touch.
If it earns a place on your desktop, help keep it growing.