MOMO CODE
███╗   ███╗ ██████╗ ███╗   ███╗ ██████╗    ██████╗ ██████╗ ██████╗ ███████╗
████╗ ████║██╔═══██╗████╗ ████║██╔═══██╗  ██╔════╝██╔═══██╗██╔══██╗██╔════╝
██╔████╔██║██║   ██║██╔████╔██║██║   ██║  ██║     ██║   ██║██║  ██║█████╗
██║╚██╔╝██║██║   ██║██║╚██╔╝██║██║   ██║  ██║     ██║   ██║██║  ██║██╔══╝
██║ ╚═╝ ██║╚██████╔╝██║ ╚═╝ ██║╚██████╔╝  ╚██████╗╚██████╔╝██████╔╝███████╗
╚═╝     ╚═╝ ╚═════╝ ╚═╝     ╚═╝ ╚═════╝    ╚═════╝ ╚═════╝ ╚═════╝ ╚══════╝

AI-powered coding agent that evolves with you.
Built on opencode with a unique dual-speed self-evolution system based on Pioneer Agent.
⚠️ Experimental / Active Development
v2.0 重大架构升级中。 当前版本引入了 Pi 框架集成、RSI 自进化循环和 JEV 决策层。v1.x 的 /evolve、/fine-tune 等命令继续兼容,但内部实现将逐步迁移到新架构。
🚀 v2.0 新特性
1. Pi 框架集成(Extension 模式)
- 以 npm 依赖形式集成
@earendil-works/pi-coding-agent@1.1.0,非 fork - 6 个 momo 专属 Pi 扩展:
experience— 自动注入历史验证过的战术rsi— 采集工具调用结果与会话指标permissions— 敏感操作(写入/危险命令)Y/n 确认decisions— L0 决策胶囊实时显示cot— 思维链面板(⌃T 折叠/展开)brand— momo 品牌 Banner
2. 统一 CLI 入口
momo                              # 进入交互式 REPL(默认)
momo "帮我写一个快速排序"          # 单次任务模式
momo exec "任务描述"               # 显式单次执行
momo --json "任务描述"             # JSONL 结构化输出
momo /evolve --demo               # v1.x 遗留命令(兼容)
3. 交互式 REPL
>prompt 交互输入/help/exit/cot内置命令⌃T— 展开/折叠思维链⌃O— 切换工具详情⌃C— 中断退出
4. JEV 决策层(Judgment-Evaluation-Verification)
- 5 个决策门:tool / tactic / route / diff / promote
- 影子模式:并行记录 JEV 决策与 LLM 决策,校准 ECE
- 支持多后端:TypeSafe(推荐)、Kev、Laya-MLX、规则降级
5. RSI 自进化循环(3 级)
| 层级 | 范围 | 自动化程度 |
|---|---|---|
| R1 Product | 提示词补丁、战术参数 | 全自动 |
| R2 Strategy | L0 决策模型权重 | 自动 + 校准门 |
| R3 Mechanism | 评估器本身 | 仅生成提案,需人工 Review |
- 预算控制:日限额、成本上限、并发实验数
- 安全开关:
touch ~/.momo/STOP立即停止
6. momo-bench 评估框架
- 三层切分:selection(60%) / holdout(30%) / canary(10% 冻结)
- 晋升门:7 个反向测试防止作弊
- 任务隔离:快照 + 验证器分离 + 预算限制
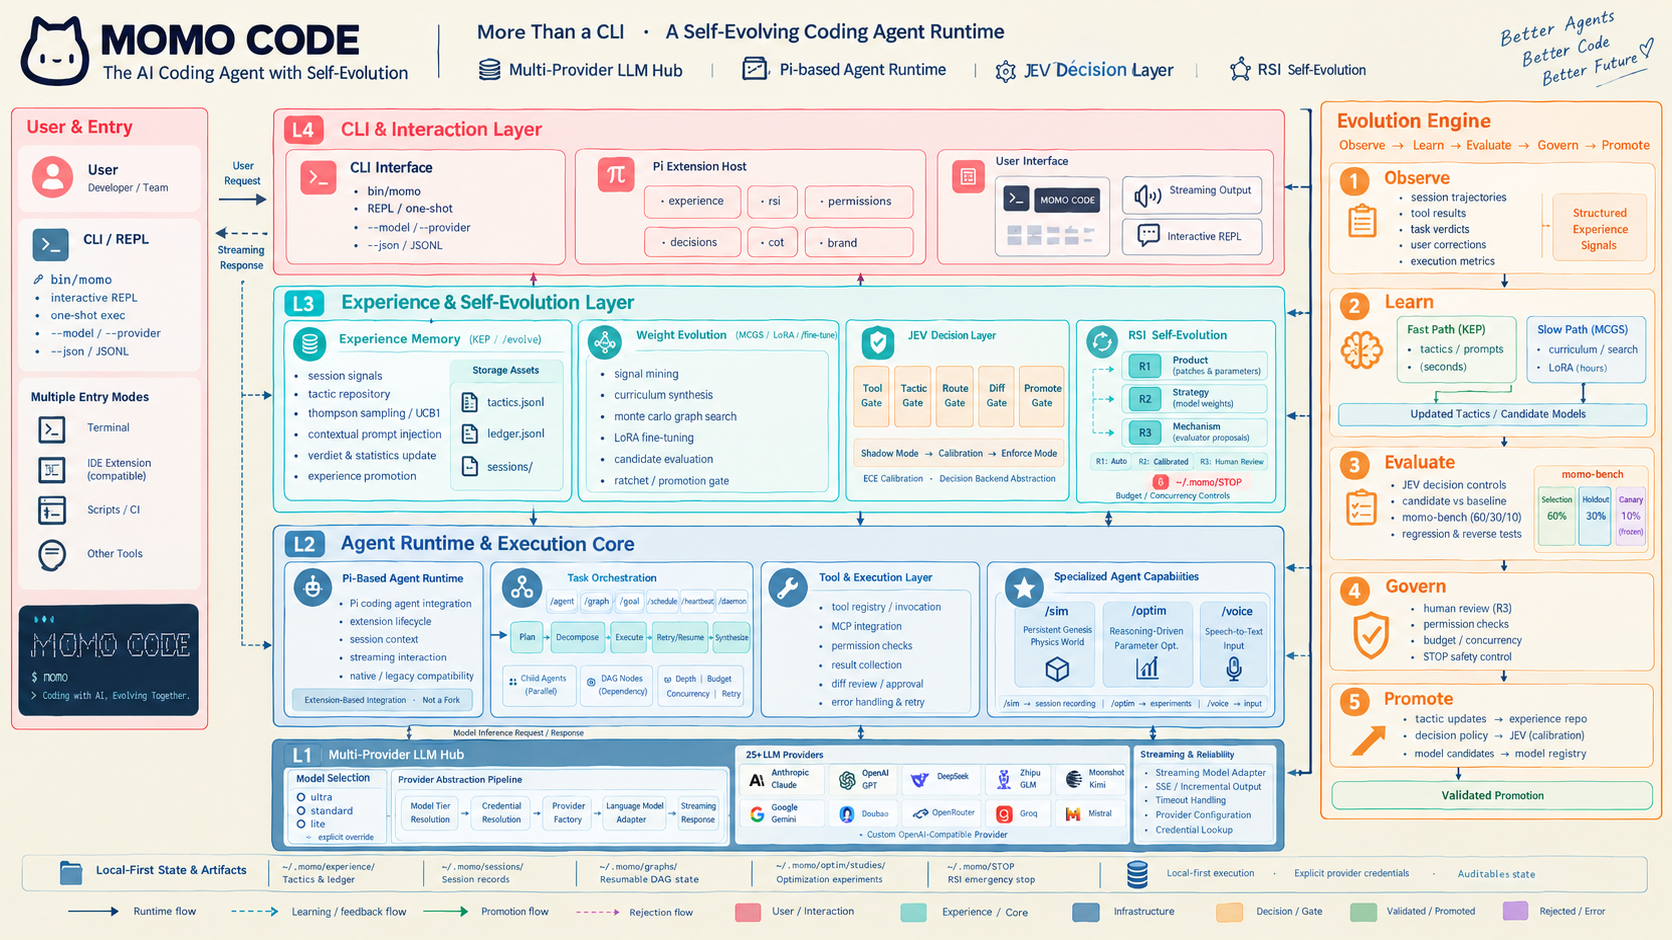
Architecture
| Two-Speed Evolution Algorithm | System Technical Architecture |
|---|---|
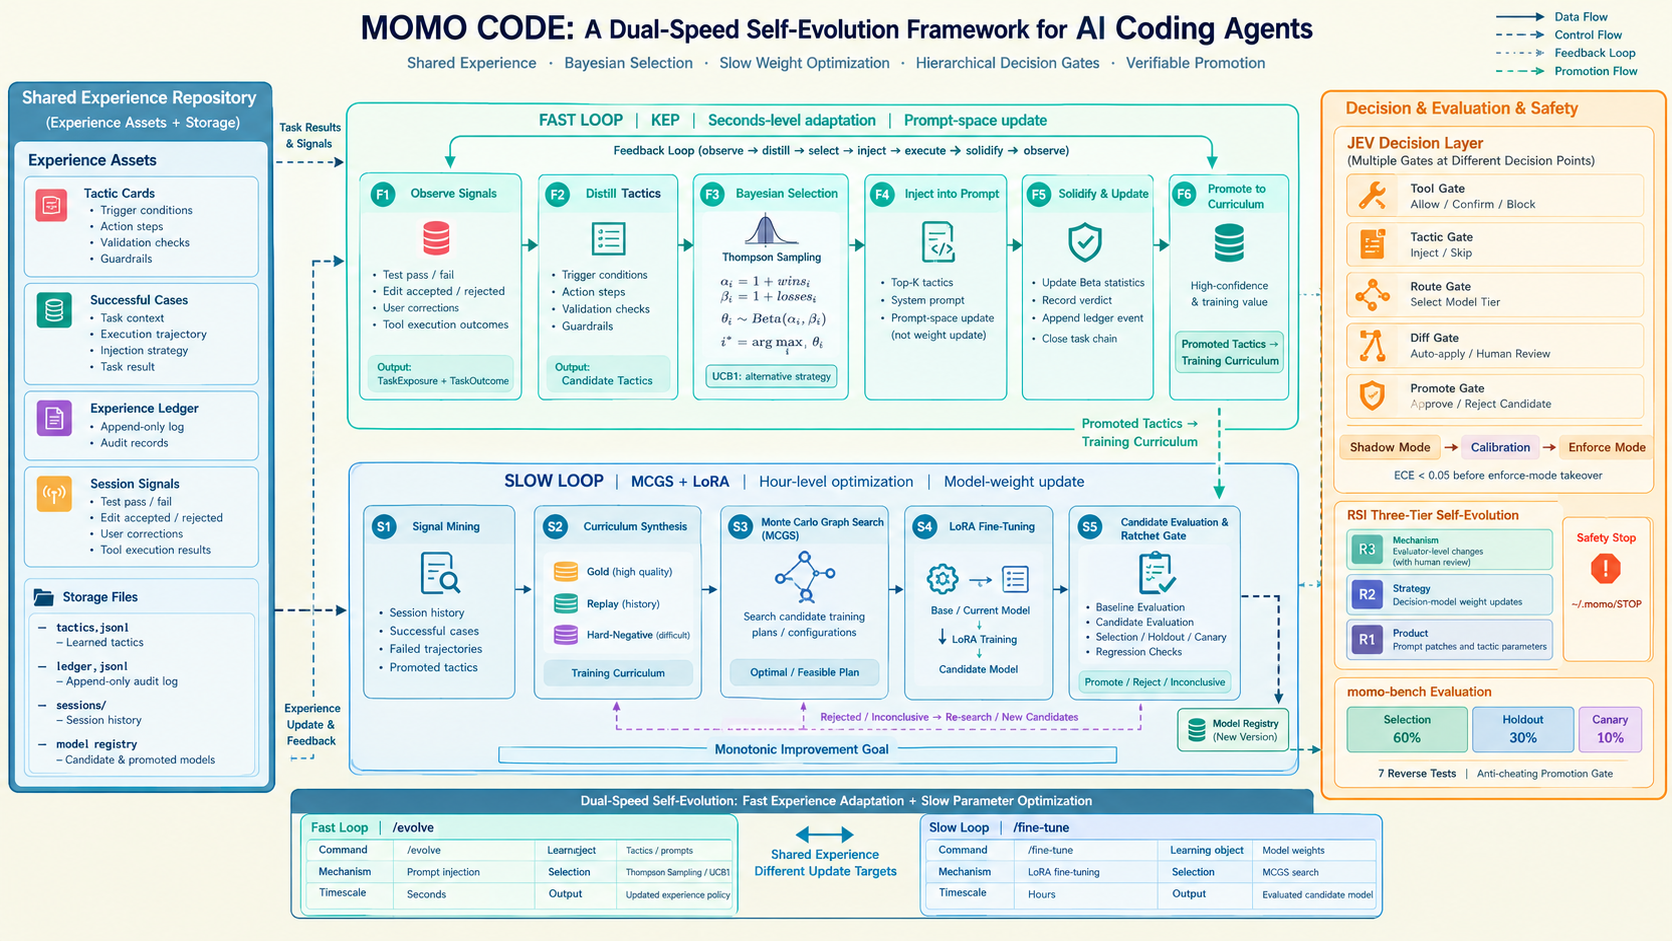 |
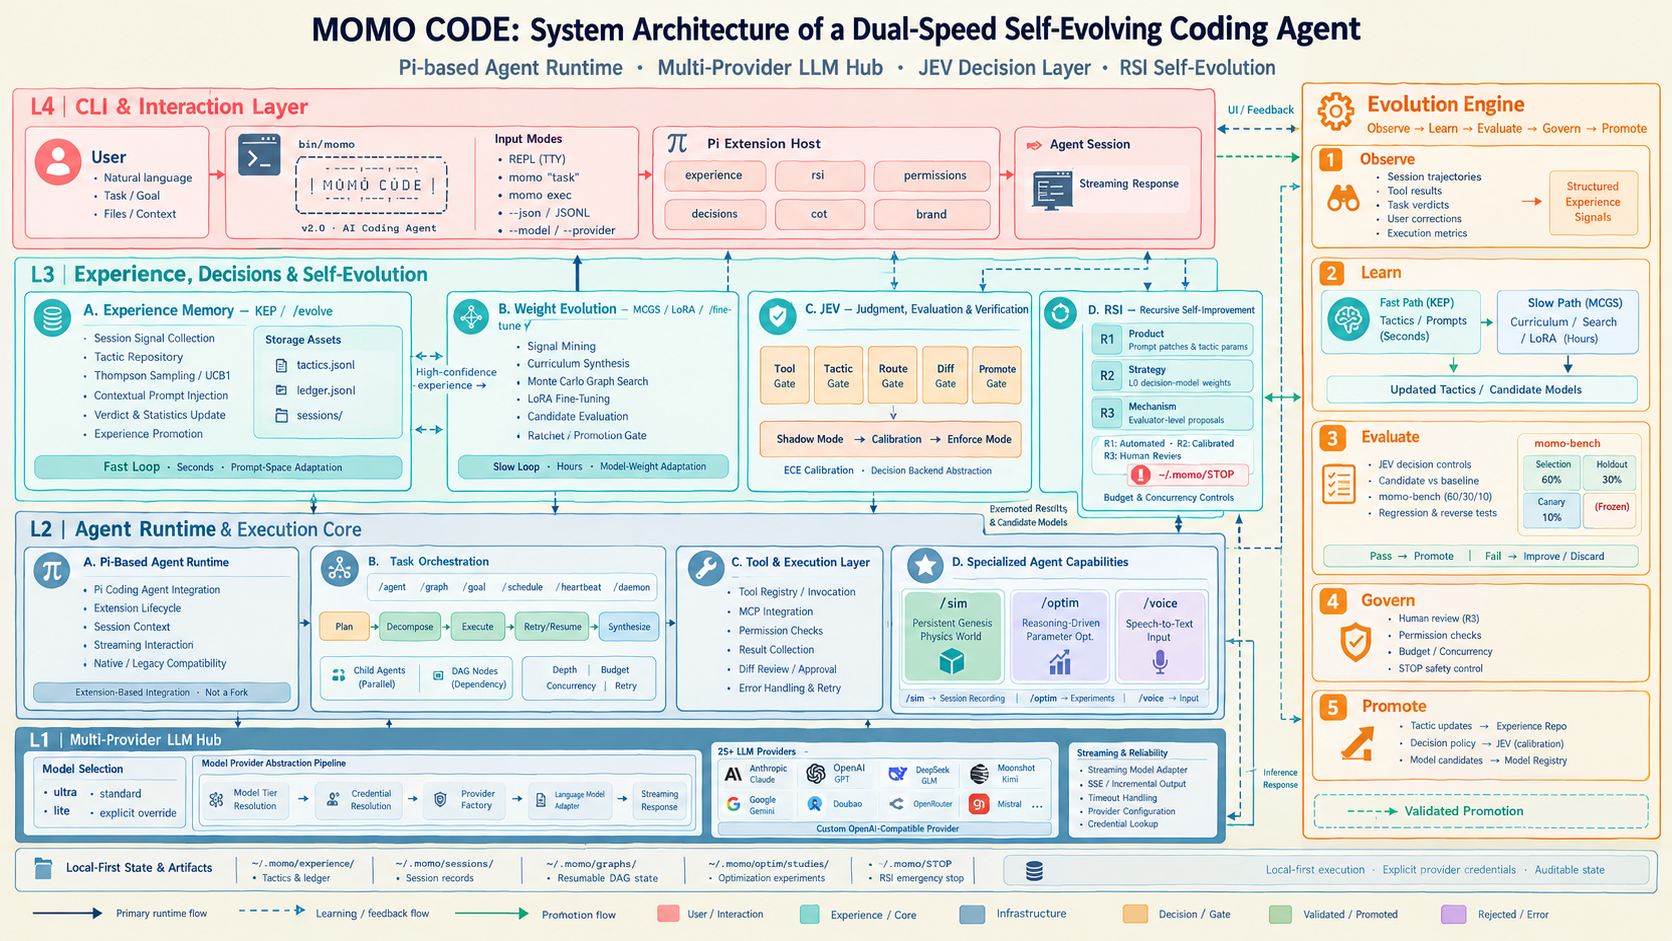 |
Table of Contents
- Features
- Installation
- Quick Start
- Usage
- CLI Commands
- Configuration
- Experience Fast Loop (
/evolve) - Self-Evolution Training (
/fine-tune) - v2.0 Architecture
- Migrating from Claude Code
- Environment Variables
- Architecture
- Changelog
- License
Features
- 25+ LLM Providers — Deepseek, Zhipu (GLM), Moonshot (Kimi), Claude, GPT-4, Gemini, Doubao, OpenRouter, Groq, Mistral, and more. The
\chatcommand uses OpenAI-compatible protocol only - Custom Provider — Plug in any OpenAI-compatible API with
MOMO_CUSTOM_*env vars - Model Tiers — Zero-config selection:
ultra/standard/lite - Interactive REPL — v2.0 native TTY interface with CoT panel, decision chips, keyboard shortcuts
- Pi Framework Integration — v2.0 extension-mode agent runtime with 6 momo-specific extensions
- JEV Decision Layer — Shadow-mode L0 decision model with ECE calibration
- RSI Self-Evolution — 3-tier recursive improvement (R1/R2/R3) with budget rails and STOP guard
- momo-bench — 3-tier evaluation (selection/holdout/canary) with 7 reverse tests
- Experience Fast Loop (
/evolve) — Second-level prompt injection via KEP protocol. Tactics distilled from success are auto-selected via Thompson sampling - Self-Evolution Training (
/fine-tune) — Hour-level weight improvement via Monte Carlo Graph Search (MCGS) + LoRA - Self-Refinement (
/refine) — Reviews session trajectories and proposes small, evidence-based improvements (tactics/prompt patches) that only take effect after human approval - Recursive Subagents (
/agent) — RLM-style task decomposition: plan → parallel child processes → synthesis, with depth/budget rails - Graph Engine (
/graph) — Long-horizon tasks as a resumable DAG of subagents: LLM-planned dependency graph, parallel execution, retries, and/simworld-agent nodes - Long-Running Work (
/goal+/heartbeat+/daemon) — Persistent goals injected into every session, timed tasks, and a daemon loop for multi-hour autonomy - Simulation Agent (
/sim) — LLM-driven control of a persistent Genesis physics world: the agent writes Python into a long-lived namespace (RLM-style), with skills-as-code loaded from~/.momo/sim/skills/ - Voice Input (
/voice) — Speak your prompt: mic recording (sounddevice) → OpenAI-compatible STT (Whisper/Groq) → coding session - Claude Code Interop — Seamless migration, inherits
.claude/config, MCP servers, prompts - Local-first — Your code never leaves your machine. Open source, auditable
- Effect-powered — Built with Effect for composable, type-safe code
Installation
Prerequisites
- macOS or Linux (Windows via WSL)
- Node.js ≥ 20.0.0 — install from https://nodejs.org if you don't have it
- git and curl
Check with:
node -v   # should print v20.x or later
npm -v
git --version
curl --version
Quick install (recommended)
curl -fsSL https://momozi.cc/install | bash
The installer:
- Clones the repo into
~/.momo/lib/momo-code - Runs
npm install+npm run build(about 30-60 s) - Drops a wrapper at
~/.momo/bin/momo - Appends
~/.momo/binto your PATH in~/.zshrcor~/.bashrc
Open a new terminal (or run source ~/.zshrc) and then:
momo --version    # 1.0.0
momo --help
If you see command not found: momo, your PATH didn't pick up the change — see INSTALL.md.
From source (manual)
git clone https://github.com/momozi1996/momo-code.git
cd momo-code/packages/opencode
npm install                # installs all deps including TypeScript + Pi framework
npm run build              # compiles TS + fixes ESM imports
npm run smoke              # run smoke tests (23 checks)
node bin/momo --version
Note: If
npm installfails to fetch@earendil-works/pi-coding-agent(network issues), the CLI automatically falls back to momo Native REPL (simulation mode). All other features remain usable.
From npm
npm package coming in v1.1. Use the Quick install above for v1.0.
Uninstall
# Remove install artifacts
rm -rf ~/.momo

# Remove the PATH line from your shell rc
sed -i.bak '/# momo Code CLI/,+1d' ~/.zshrc    # zsh
sed -i.bak '/# momo Code CLI/,+1d' ~/.bashrc   # bash
Quick Start
1. Set up API key
# Generic key (works with any provider)
export MOMO_API_KEY=your-api-key

# Or provider-specific
export MOMO_ANTHROPIC_API_KEY=sk-ant-...
export MOMO_OPENAI_API_KEY=sk-...
2. Start coding
# Interactive REPL (v2.0 default)
momo

# One-shot task
momo "Refactor auth to use Effect"

# Use a model tier
momo --model ultra "Complex architecture review"
momo --model standard "Fix the login bug"
momo --model lite "Quick code review"

# JSONL structured output (v2.0)
momo --json "Generate a todo app"

# Legacy one-shot (v1.x compatible)
momo -p anthropic "task"
3. First run
On first run, momo creates ~/.momo/:
~/.momo/
├── momo.jsonc          # Config
├── sessions/           # History
├── experience/         # Learned tactics (auto-created)
│   ├── tactics.json
│   └── ledger.jsonl
├── rsi-meta.json       # RSI loop metadata (v2.0)
└── STOP                # Safety halt file (create to stop RSI)
Usage
Model Tiers
| Tier | Use Case |
|---|---|
ultra |
Complex tasks, large context |
standard |
Daily coding work |
lite |
Quick tasks, low latency |
CLI Options
momo [options] [prompt]

Options:
  --model, -m        Model ID or tier
  --provider, -p   Provider
  --json                 JSONL structured output (v2.0)
  --help                 Show help
  --version              Show version
CLI Commands
Interactive REPL (v2.0)
momo                     # Enter interactive REPL
momo "prompt"            # One-shot task (auto-detects TTY)
momo exec "prompt"       # Explicit single-run mode
momo --json "prompt"     # JSONL event stream output
REPL built-in commands:
| Command | Description |
|---|---|
/help |
Show help |
/exit |
Exit REPL |
/cot |
Toggle CoT display |
Keyboard shortcuts:
| Shortcut | Action |
|---|---|
⌃T |
Expand/collapse thinking chain |
⌃O |
Toggle tool details |
⌃C |
Interrupt / exit |
Coding Session (Legacy)
momo                     # Show help and banner
momo "prompt"            # One-shot task
momo --model claude-sonnet-4 "task"
Experience Fast Loop (/evolve)
momo /evolve                       # Run evolution with default settings
momo /evolve --mode=explore        # Favor exploration of new tactics
momo /evolve --mode=harden         # Favor proven high-win-rate tactics
momo /evolve --mode=convention-only # Only convention-type tactics
momo /evolve --list                # Show all learned tactics
momo /evolve --inject              # Inject tactics for current task
momo /evolve --solidify            # Apply verdict, update stats
Self-Evolution Training (/fine-tune)
momo /fine-tune              # Diagnose, show training proposal
momo /fine-tune run          # Execute training pipeline
momo /fine-tune run --dry-run # Preview without executing
momo /fine-tune status       # Check training status
momo /fine-tune promote      # Promote candidate to production
Self-Refinement (/refine)
Reviews recent session trajectories and proposes small, reviewable improvements. Nothing is applied without human approval.
momo /refine                 # Generate proposals from recent sessions
momo /refine list            # List proposals
momo /refine show        # Inspect evidence + content
momo /refine approve     # Approve (review gate)
momo /refine apply       # Apply: tactic → draft, patch → prompt file
momo /refine reject      # Reject
Recursive Subagents (/agent)
RLM-style recursion: the model decomposes a complex task, subagents run
as child momo processes (parallel where possible), and a synthesizer
merges results.
momo /agent "Refactor the provider layer and update all callers and tests"
Rails: MOMO_RLM_MAX_DEPTH (3), MOMO_RLM_BUDGET (8), MOMO_RLM_TIMEOUT_MS (300000).
Graph Engine (/graph)
Turns a long-horizon task into a directed acyclic graph of self-contained
subagent tasks. The model plans the DAG (with real dependencies), nodes run as
child momo processes — in parallel per topological level, with dependency
outputs passed downstream — failed nodes retry, and a final LLM pass
synthesizes the report. State persists to ~/.momo/graphs/.json after
every batch, so runs survive restarts.
momo /graph run "Design + implement + test a persistence layer"   # plan → execute → synthesize
momo /graph resume         # Continue a long-horizon run where it stopped
momo /graph status         # Node states + outputs
momo /graph list               # Recent runs
Nodes can be marked "kind": "sim" by the planner — those become simulation
agents driving the Genesis world via /sim run, so a graph can mix coding
subagents with physics experiments.
Rails: MOMO_GRAPH_MAX_NODES (12), MOMO_GRAPH_MAX_RETRIES (2),
MOMO_GRAPH_CONCURRENCY (defaults to MOMO_RLM_BUDGET).
Long-Running Work (/goal, /schedule, /heartbeat, /daemon)
momo /goal add "Ship v2.0" "with full test coverage"   # Persistent goal
momo /goal list | log  "progress" | done       # Manage goals
momo /schedule add --every=60m "run tests and report"  # Timed task
momo /schedule add --at=07:30 "daily standup summary"  # Daily task
momo /heartbeat            # Run due tasks once
momo /daemon               # Foreground loop (Ctrl+C to stop)
Active goals are injected into every chat session. The daemon is a
foreground process by design — background it with nohup/systemd/Task
Scheduler. Budget rails: MOMO_DAEMON_MAX_RUNS, MOMO_DAEMON_MAX_HOURS (24).
Simulation Agent (/sim)
An LLM-driven agent that controls a persistent Genesis
physics world. Requires Python with genesis-world installed
(pip install genesis-world).
momo /sim doctor                      # Check python/genesis/provider setup
momo /sim run "Stack the red cube on the blue cube"   # LLM control loop
momo /sim run "" --steps=40 --viewer            # Budget + live viewer
momo /sim exec "print(42)"            # One-shot world REPL
momo /sim exec --file=scene.py        # Run a script in a fresh world
momo /sim skills                      # List installed world skills
momo /sim eval --tasks=tasks.json     # Batch evaluation (fresh world per episode)
How it works: the CLI spawns a persistent Python process
(python/genesis_world/server.py) holding a Genesis scene. Each loop
step, the model replies with {"thought": ..., "code": ...}; the code
runs in the persistent world namespace (gs, scene, step(n), your
variables survive across steps). Skills are plain .py files dropped
into ~/.momo/sim/skills/ — auto-loaded into every world. Sim runs are
recorded as trajectories, feeding the /refine self-improvement loop.
Env: MOMO_SIM_PYTHON, MOMO_SIM_BACKEND (cpu/gpu),
MOMO_SIM_MAX_STEPS (20), MOMO_SIM_SERVER.
Reasoning-Driven Optimization (/optim)
Parameter tuning driven by code understanding + explicit reasoning
(inspired by optim-agent).
The agent reads your code first and infers the physical/business meaning of
every parameter, then proposes configurations with explicit _reasoning and
a _note scratchpad fed forward across trials. Invalid proposals degrade to
random sampling — a flaky agent can never crash a study.
momo /optim scan src/serve.py --param=threshold:0.05:0.95   # read code → semantic map
momo /optim init quality --target=src/serve.py \
  --param=threshold:0.05:0.95 --param=budget:10:200:int,log \
  --metric=score --direction=max --cmd="python eval.py --threshold {threshold}"
momo /optim semantics quality approve     # human review gate
momo /optim run quality --trials=20       # reasoning-driven loop
momo /optim history quality               # full reasoning trace
Evaluators: --cmd (business command, metric from stdout) or --sim
(experiment in the Genesis world, ESTOP-honored). Studies persist under
~/.momo/optim/studies// and resume automatically. See
docs/optim.md.
Env: MOMO_OPTIM_HISTORY (5), MOMO_OPTIM_N_INIT (2), MOMO_OPTIM_TIMEOUT (300).
Local Server & Dashboard (serve)
A zero-dependency local HTTP server that exposes momo's state as a JSON API + SSE live feed, with a single-file dashboard (no build step).
momo serve                      # http://127.0.0.1:4097 (dashboard at /)
momo serve --port=8080 --token=s3cret
- API:
GET /api/sessions|goals|schedule,GET /api/optim/studies[/:name[/trials]],GET /api/sim/observe, SSEGET /api/optim/studies/:name/stream - Actions:
POST /api/optim/studies/:name/run,POST /api/sim/estop|resume,POST /api/chat - Dashboard tabs: Overview / Sessions / Optim (live reasoning trace + best-so-far chart) / Sim (ESTOP control) / Schedule & Goals / Chat
- Binds loopback by default; non-loopback requires
--token(Bearer auth,?token=fallback for browser EventSource)
Env: MOMO_SERVE_PORT (4097), MOMO_SERVE_HOST (127.0.0.1), MOMO_SERVE_TOKEN.
Voice Input (/voice)
Speak your prompt instead of typing. Requires pip install sounddevice scipy
for recording, and an OpenAI-compatible speech-to-text endpoint.
momo /voice                       # Record 5s → transcribe → run as prompt
momo /voice --seconds=10 --lang=zh
momo /voice --file=meeting.mp3    # Transcribe an audio file → run
momo /voice transcribe --file=x.wav  # Print transcription only
export MOMO_STT_API_KEY=sk-...       # falls back to MOMO_OPENAI_API_KEY / MOMO_API_KEY
export MOMO_STT_MODEL=whisper-1      # default
# Groq (fast, generous free tier):
export MOMO_STT_BASE_URL=https://api.groq.com/openai/v1
export MOMO_STT_MODEL=whisper-large-v3
Models
momo models list         # List all models
momo models info     # Show model details
momo models providers    # Show available providers
Configuration
Config File (~/.momo/momo.jsonc)
{
  "$schema": "https://momozi.cc/config.json",
  "model": "standard",
  "provider": "anthropic",
  "inheritClaudeCode": true,
  "evolve": {
    "enabled": true,
    "auto": false,
    "clusterThreshold": 10,
    "budgetUSD": 50
  }
}
v2.0 Config Schema (momo.jsonc v2)
v2.0 introduces an extended config schema supporting Pi runtime, JEV, RSI, and UI settings:
| Section | Key | Description | Default |
|---|---|---|---|
runtime |
engine |
Agent engine: pi or legacy |
pi |
decision |
mode |
JEV mode: shadow/enforce/off |
shadow |
decision |
points |
Active decision gates | ["tactic-relevance"] |
experience |
maxInjectedTactics |
Max tactics per prompt | 3 |
rsi |
mode |
RSI mode: observe/auto/off |
observe |
rsi |
maxCampaignCostUsd |
Max cost per campaign | 5 |
rsi |
stopFile |
Halt signal file path | ~/.momo/STOP |
ui |
thinking |
CoT display: collapsed/expanded/off |
collapsed |
Experience Fast Loop (/evolve)
The experience fast loop (KEP — Knowledge Embedding Protocol) is momo's unique second-level learning system. Unlike /fine-tune which updates model weights over hours, /evolve learns and applies knowledge in seconds via prompt injection.
How it works
- Observe — Extract signals from sessions (test pass/fail, edit accepted/rejected, user corrections)
- Distill — Convert successful patterns into compact Tactic cards
- Select — Rank tactics via Thompson sampling (Bayesian explore/exploit)
- Inject — Insert top-k tactics into the system prompt for the current task
- Solidify — Apply verdict, update Beta distribution statistics
- Promote — High-confidence tactics graduate to
/fine-tunecurriculum
Three KEP Assets
| Asset | Description |
|---|---|
| Tactic | Compact strategy card with triggers, steps, checks, guardrails |
| Case | Successful task record with injected tactics |
| Ledger | Append-only audit log (JSONL) |
Tactic Statistics (Beta Distribution)
Each tactic tracks a Beta(α, β) distribution:
- α = 1 + wins, β = 1 + losses
- Thompson sampling for exploration/exploitation balance
- UCB1 as alternative selection strategy
Evolution Modes
| Mode | Behavior |
|---|---|
balanced (default) |
Normal explore/exploit trade-off |
explore |
Favor new tactics, wider sampling |
harden |
Favor proven tactics, tighter selection |
convention-only |
Only convention-type tactics |
Storage
Learned tactics are stored in ~/.momo/experience/:
tactics.jsonl— All tactic recordsledger.jsonl— Audit log of all operations
Environment Variables
| Variable | Description | Default |
|---|---|---|
MOMO_XP_MODE |
Evolution mode | balanced |
MOMO_XP_DIR |
Storage directory | ~/.momo/experience |
Self-Evolution Training (/fine-tune)
The weight slow loop improves momo's model weights via fine-tuning. This runs at hour-level timescales.
How it works
- Signal Mining — Extract learning signals from sessions
- Curriculum Synthesis — Build training data (Gold/Hard-neg/Replay slices)
- Monte Carlo Graph Search (MCGS) — Explore training pipeline space
- LoRA Fine-tuning — Train candidate model
- Ratchet Gate — Ensure monotonic improvement
Commands
momo /fine-tune              # Diagnose, show proposal
momo /fine-tune run          # Execute training
momo /fine-tune run --dry-run # Preview
momo /fine-tune status       # Check status
momo /fine-tune promote      # Promote candidate
Configuration
| Variable | Description | Default |
|---|---|---|
MOMO_EVOLVE_ENABLED |
Enable self-evolution | true |
MOMO_EVOLVE_AUTO |
Auto-trigger training | false |
MOMO_EVOLVE_BUDGET_USD |
Max training budget | 50 |
v2.0 Architecture
Pi Extension Architecture
momo v2.0 integrates Pi as an npm dependency (not a fork), loading 6 custom extensions into Pi's AgentSessionRuntime:
Pi AgentSessionRuntime
├── momo-brand          # Show ASCII banner on start
├── momo-experience     # Inject tactics into system prompt
├── momo-permissions    # Y/n gate for write/dangerous ops
├── momo-decisions      # Show L0 decision capsules
├── momo-cot            # Thinking chain panel (⌃T toggle)
└── momo-rsi            # Record tool_result + agent_settled
JEV Decision Layer
Shadow-mode L0 decision model with 5 gates:
| Gate | Purpose |
|---|---|
tool |
Allow / confirm / block tool execution |
tactic |
Inject tactic or not |
route |
Select model tier (ultra/standard/lite) |
diff |
Auto-apply diff or request human review |
promote |
Approve RSI candidate promotion |
Calibration: ECE < 0.05 before enforce mode takeover.
RSI 3-Tier Loop
| Tier | Scope | Frequency | Human Review |
|---|---|---|---|
| R1 Product | Prompt patches, tactic params | Every session | No |
| R2 Strategy | L0 decision model weights | Per calibration gate | Gate-triggered |
| R3 Mechanism | Evaluator itself | Rare | Required |
Safety: touch ~/.momo/STOP halts all RSI activity immediately.
momo-bench Evaluation
Three-tier data split preventing overfit:
| Split | Ratio | Purpose |
|---|---|---|
| selection | 60% | Tactic optimization |
| holdout | 30% | Gate validation |
| canary | 10% | Frozen — never seen by auto-pipeline |
Promotion gate includes 7 reverse tests (cheating prevention):
- Obviously broken tactic → reject
- Delete tests to pass → reject
- Fake score with exit nonzero → reject
- Identical to baseline → inconclusive
- Cost down, no regression → accept
- Insufficient data → inconclusive
- Improve dev, hurt holdout → reject
Project Structure (v2.0)
packages/opencode/src/
├── cli/                 # v1.x legacy commands (/evolve /fine-tune)
├── config/              # momo.jsonc v2 schema + resolver
├── decision/            # DecisionPort type contract
├── evolve/              # Evolution + EvolutionCandidate
├── experience/          # KEP fast loop + closure chain
├── jev/                 # JEV decision layer
├── momo-bench/          # 3-tier evaluation + gate
├── pi-extensions/       # 6 Pi extensions
├── provider/            # 19 LLM provider integrations
├── repl/                # Interactive TTY REPL
├── rsi/                 # 3-tier self-evolution loop
├── runtime/             # TaskResult + event envelopes
├── session/             # Prompt routing
├── test/                # Smoke + integration tests
└── effect/              # Effect utilities
Migrating from Claude Code
Zero-friction migration:
- Config inheritance (default ON) —
~/.claude/settings.jsonauto-merged - MCP servers (default ON) —
.claude/mcp/work out of the box - Prompts (default ON) —
.claude/prompts/available
# Disable inheritance
export MOMO_CLAUDE_CODE_INHERIT=false
export MOMO_ONLY=1
Environment Variables
| Variable | Description | v2.0 |
|---|---|---|
MOMO_API_KEY |
Generic API key | |
MOMO_HOME |
Home directory (default: ~/.momo) |
|
MOMO_MODEL |
Default model/tier | |
MOMO_PROVIDER |
Default provider | |
MOMO_UI_DECISION_CHIPS |
Show decision capsules | ✅ |
MOMO_UI_EVIDENCE_BAR |
Show evidence bar | ✅ |
MOMO_RSI_ENABLED |
Enable RSI signal recording | ✅ |
MOMO_RSI_MAX_PROMOTIONS_PER_DAY |
Daily promotion limit | ✅ |
MOMO_RSI_MAX_COST |
Max campaign cost (USD) | ✅ |
MOMO_XP_MODE |
Evolution mode (balanced/explore/harden/convention-only) | |
MOMO_XP_DIR |
Experience storage dir | |
MOMO_SESSION_RECORD |
Set false to disable session trajectory recording |
|
MOMO_RLM_MAX_DEPTH |
Subagent recursion limit (default: 3) | |
MOMO_RLM_BUDGET |
Max subagents per orchestration (default: 8) | |
MOMO_DAEMON_INTERVAL |
Daemon poll seconds (default: 60) | |
MOMO_DAEMON_MAX_RUNS / MOMO_DAEMON_MAX_HOURS |
Daemon budget rails | |
MOMO_SIM_PYTHON |
Python executable for the sim world server | |
MOMO_SIM_BACKEND |
Genesis backend: cpu or gpu (default: cpu) | |
MOMO_SIM_MAX_STEPS |
Max LLM control-loop steps (default: 20) | |
MOMO_STT_API_KEY |
STT key for /voice (OpenAI-compatible) | |
MOMO_STT_BASE_URL / MOMO_STT_MODEL |
STT endpoint/model (default: OpenAI whisper-1) | |
MOMO_VOICE_SECONDS |
Default voice recording length (default: 5) | |
MOMO_EVOLVE_ENABLED |
Enable self-evolution | |
MOMO_EVOLVE_BUDGET_USD |
Training budget | |
MOMO_ANTHROPIC_API_KEY |
Anthropic key | |
MOMO_OPENAI_API_KEY |
OpenAI key | |
MOMO_OPENROUTER_API_KEY |
OpenRouter key |
Full list: src/env.ts
Architecture
Dual-Speed Evolution
┌─────────────────────────────────────────────────────────┐
│                    momo Code                             │
├─────────────────────┬───────────────────────────────────┤
│  Experience Fast    │  Weight Slow Loop                 │
│  Loop (/evolve)     │  (/fine-tune)                     │
├─────────────────────┼───────────────────────────────────┤
│  Timescale: seconds │  Timescale: hours                 │
│  Mechanism: prompt  │  Mechanism: LoRA fine-tuning      │
│   injection         │                                   │
│  Selection:         │  Search: Monte Carlo Graph        │
│   Thompson/UCB      │   Search (MCGS)                   │
│  Storage: JSONL     │  Training: LoRA                   │
│   (~/.momo/xp/)     │  Gate: Ratchet check              │
│  Bridge: promoted   │  Storage: model registry          │
│   → curriculum      │                                   │
└─────────────────────┴───────────────────────────────────┘
Provider Layer
User Request
    |
    v
resolveModel("standard") → BUILTIN_TIERS.standard
    |                           [claude-sonnet, gpt-4.1, ...]
    v
getCredentials() → MOMO_*_API_KEY env
    |
    v
Provider Factory → baseUrl, headers, timeout
    |
    v
createModel() → LanguageModel adapter
    |
    v
wrapSSE() → Streaming with 8min timeout
Test Results
- TypeScript:
tsc --noEmit— 0 errors - Smoke Test: 23/23 checks passed
- CLI verified: REPL,
/evolve,/fine-tune,models,help
Changelog
v2.0.0 (2026-10-11)
Added:
- Pi framework integration (
@earendil-works/pi-coding-agent@1.1.0) as extension dependency - Interactive REPL with CoT panel, decision capsules, keyboard shortcuts
- JEV decision layer — 5 gates with shadow mode and ECE calibration
- RSI 3-tier self-evolution loop (R1/R2/R3) with budget rails and STOP guard
- momo-bench — 3-tier evaluation (selection/holdout/canary) + 7 reverse tests
- 6 Pi extensions: experience, rsi, permissions, decisions, cot, brand
- DecisionPort type contract with choice/bool/score/abstain kinds
- TaskResult + EventEnvelope types for structured logging
- EvolutionCandidate interface with CAS promotion guard
- Experience closure chain (TaskExposure → TaskOutcome → Solidify)
- momo.jsonc v2 config schema with priority resolver
Changed:
- Rewrote
bin/momoas unified entry (REPL / Pi / legacy fallback) - Version: 0.1.1 → 1.0.0
- Added
[SIMULATED]warnings to all placeholder random data - Added
NOTICEfile for independent copyright declaration - LICENSE: clarified as THIRD-PARTY DEPENDENCIES (Pi is a dependency, not a fork)
v1.0.0 (2026-06-16)
Added:
- Experience fast loop (
/evolve) — KEP protocol with Thompson sampling - Weight slow loop (
/fine-tune) — MCGS training pipeline - CLI command system —
/evolve,/fine-tune,models,help - 53 TypeScript modules across provider/evolve/experience/cli layers
- Dual-speed evolution architecture
- Beta distribution tracking for tactic selection
- Two-speed bridge (promoted tactics → fine-tune curriculum)
Changed:
- Product name: kqq Code → momo Code
- bin/momo: CJS → ESM command router
- package.json: Production-ready exports, files whitelist
License
MIT — see NOTICE for third-party attributions.
See USE_RESTRICTIONS.md and SECURITY.md.